17 The open model revolution of 2026
This chapter covers
- GLM-5: a 744B-parameter MoE model
- Qwen3-Coder-Next: Sparse MoE for coding
- MiniMax M2.5: Coding benchmarks and cost
- The economics of open models
- The Unsloth-to-Ollama pipeline
- Practical steps for trying these models
In February 2026, the AI landscape shifted fundamentally. Within a single ten-day window, multiple open source models reached, and in some cases surpassed, the performance of the best proprietary AI systems. This chapter explains what happened, why it matters, and what you can do with these new capabilities.
17.1 February 2026: A turning point
Until early 2026, there was a widely held assumption in the AI industry: proprietary models from companies like OpenAI, Anthropic, and Google would always be ahead of open source alternatives. Open models were useful for learning and experimentation, but they were not frontier. Not state-of-the-art.
That assumption collapsed in February 2026. Within ten days, three separate teams released open models that matched or exceeded the best proprietary systems on major benchmarks. This was not an incremental improvement; it was a paradigm shift. The gap between what you can run on your own hardware and what the biggest companies run on their servers effectively closed.
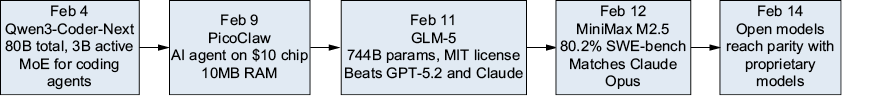
Figure 17.1 presents the timeline of what happened.
Figure 17.1 Timeline of the February 2026 open model breakthroughs, showing five major events in ten days