AdamW is an Adam variant that fixes an error in the original algorithm. It is used as the default optimizer and reduces the need for extensive learning-rate experimentation. section 5.3.2
In PyTorch, construct it with the model parameters and let its default learning rate stand unless experimentation is necessary. AdamW can train a fully connected network with behavior comparable to momentum-based SGD, while its accuracy curve is somewhat more stable. section 5.3.2
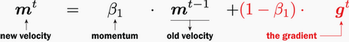
Use the accompanying training figure to compare AdamW with SGD, momentum, and Nesterov momentum. section 5.3.2
Basic PyTorch setup
fc_model.apply(weight_reset) optimizer = torch.optim.AdamW(fc_model.parameters()) fc_results_adam = train_network( fc_model, loss_func, train_loader, test_loader=test_loader, epochs=epochs, optimizer=optimizer, score_funcs={'Accuracy': accuracy_score}, device=device ) section 5.3.2
fc_model.apply(weight_reset) optimizer =
torch.optim.AdamW(fc_model.parameters())                                      #1

scheduler = torch.optim.lr_scheduler.
 CosineAnnealingLR(optimizer, epochs//3)
fc_results_adam_coslr = train_network(fc_model, loss_func, train_loader,
 test_loader=test_loader, epochs=epochs, optimizer=optimizer,
 lr_schedule=scheduler, score_funcs={’Accuracy’: accuracy_score},
 device=device)

fc_model.apply(weight_reset) optimizer =
torch.optim.SGD(fc_model.parameters(), lr=eta_0, momentum=0.9, nesterov=True) #2

scheduler = torch.optim.lr_scheduler.
 CosineAnnealingLR(optimizer, epochs//3)
fc_results_nesterov_coslr = train_network(fc_model, loss_func,
 train_loader, test_loader=test_loader, epochs=epochs,
 optimizer=optimizer, lr_schedule=scheduler,
 score_funcs={’Accuracy’: accuracy_score}, device=device)
#1 Adam with cosine annealing
#1 SGD+Nesterov with cosine annealing
Combine AdamW with CosineAnnealingLR to test whether scheduled learning rates improve accuracy. section 5.3.2


