When representative user utterances are unavailable, AI-generated data provides manufactured test examples for checking whether a classifier understands unseen requests. section 4.2.1
Use generated examples as blind test data: keep them outside the training set, run them through the classifier, and score the predicted intents. section 4.2.1
Interpret the results through:
- Accuracy, for overall correctness. section 4.2.1
- Recall, for identifying the correct intent. section 4.2.1
- Precision, for avoiding incorrect intents. section 4.2.1
Generated versus representative tests
Before deployment, generated test data can help measure understanding when actual user utterances are unavailable. After deployment, blind examples taken from user logs provide the more reliable measurement. section 4.2.1
Figure 4.5 K-fold cross validation and generated test data are suitable for situations where representative data is not available. Once a solution is deployed to production, representative blind test data will produce the most reliable measurement of your classifier’s ability to understand.
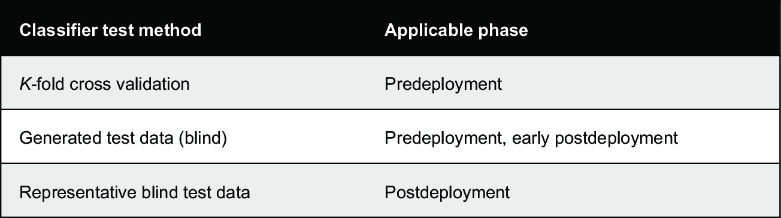
Compare k-fold cross-validation and generated test data with representative blind testing across predeployment and production contexts. section 4.2.1
