Arrow Database Connectivity (ADBC) is a cross-language, database-style API for low-latency columnar access. It uses Apache Arrow as the in-memory format, reducing serialization and copying overhead compared with traditional drivers. section 8.2.3 section 9.3.2
Within a federated lakehouse, ADBC complements JDBC and ODBC by providing a fast path for notebooks, AI platforms, and custom applications retrieving governed datasets from query engines. section 8.2.3 section 9.3.2
ADBC and its Arrow Flight foundation support:
- Large dataset retrieval with reduced serialization costs and memory overhead. section 8.2.3
- Partitioned, parallelized results and intersystem execution across distributed query engines. section 8.2.3
- Authentication tokens, parallel streams, and interoperability with Arrow Flight SQL. section 9.3.2
Figure 9.3 JDBC transfers data in a row-based format, while Apache Arrow Flight transfers data in a columnar format that’s ideal for analytics.
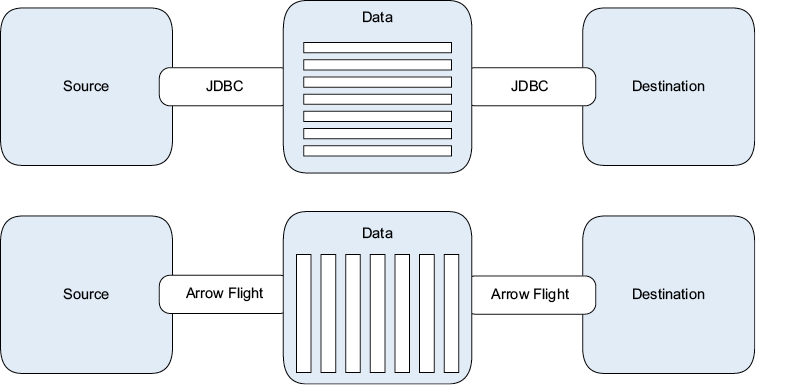
Contrasts JDBC row-based transfer with Arrow Flight columnar transport optimized for analytics. section 9.3.2
