`ollama.AsyncClient` connects `OllamaLLM` to a running Ollama service. Its `generate()` method accepts a model and prompt; the returned Ollama response can be mapped to `CompleteResult`. section 3.2 section 3.2.1
In the completion flow:
- `complete()` awaits `_client.generate()` with the instance’s model and the supplied prompt, then builds a `CompleteResult` from the response. section 3.2.1
- The client is also used through `chat()` for structured output and chat interactions. section 3.2.1
Figure 3.10 Integrating with the Ollama LLM inference framework. The OllamaLLM connects to a running Ollama server, often running locally on your machine, to work with any of the supported open-source LLMs.
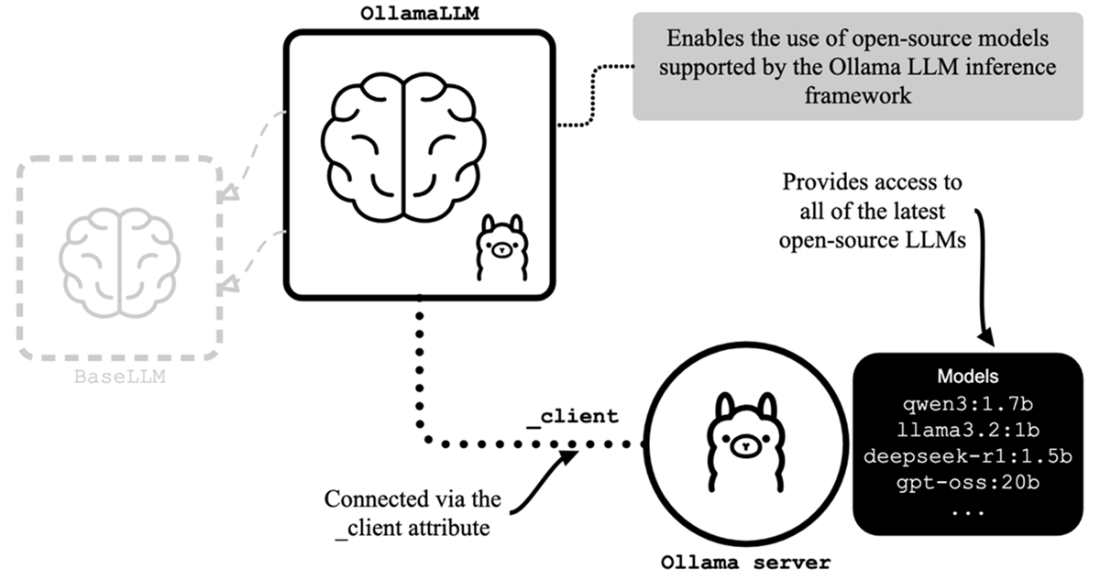
Shows the client’s role in connecting an Ollama integration to a running service. section 3.2
