Attention dilution occurs when a longer sequence spreads softmax probability mass across more tokens, preventing any single document region from receiving a dominant attention score. section 13.3
The problem complicates attention-based context pruning: weakly concentrated scores make relevant regions difficult to isolate. AttentionRAG counters it by converting a question into an answer hint prefix with one blank position, then reading attention to that focal token. section 13.3
Figure 13.2 The two obstacles to reading attention, and the answer hint prefix that resolves them. Long sequences dilute softmax mass; multi-token queries scatter focal points. Reformulating the query as a fill-in-the-blank prefix forces a single focal token whose attention concentrates on the context that informs the prediction.
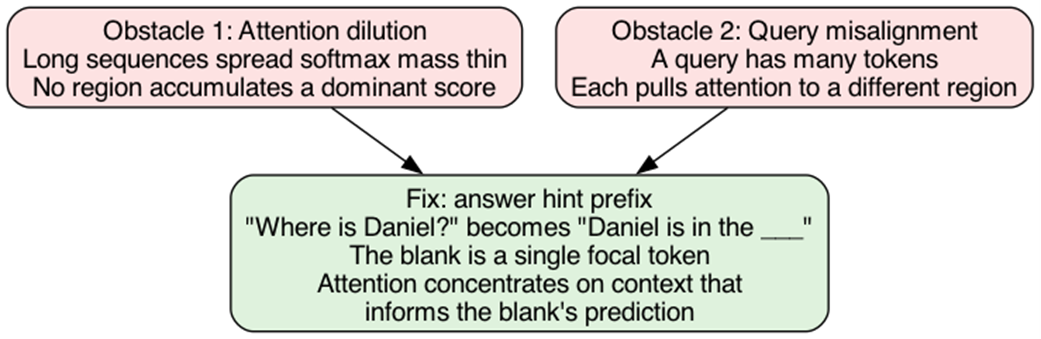
The diagram connects sequence length with diluted softmax mass and shows how a fill-in-the-blank prefix concentrates attention on the context supporting the missing answer. section 13.3
