An attention sink is a sequence position that attracts strong attention from many query positions, acting as a shared reference point for global context. In protein language models, a vertical stripe in an attention heatmap reveals this pattern; position 0 is a common location. section 12.3.3
Attention patterns distinguish several roles among Transformer heads:
- Local heads attend mainly to each position and its neighbors. section 12.3.3
- Attention-sink heads emphasize one reference position across many queries. section 12.3.3
- Other heads distribute attention broadly or connect distant residues that may interact structurally or co-evolve. section 12.3.3
Figure 12.11 Attention weights from each of the 4 heads in layer 4 (the final Transformer layer) reveal a diversity of learned patterns. Each heatmap shows query positions (Y-axis) attending to key positions (X-axis) for the sequence MKTAYIAKQRQISFVKSHFSRQLEERLGLI (~37 AAs). The viridis colormap indicates attention weight magnitude (darker purple = lower weight, brighter yellow-green = higher weight). Some heads learn to focus on local neighbors (tending towards the diagonal), while others attend to distant residues (further off-diagonal spots) or broad global context, demonstrating how the model divides the labor of understanding protein structure.
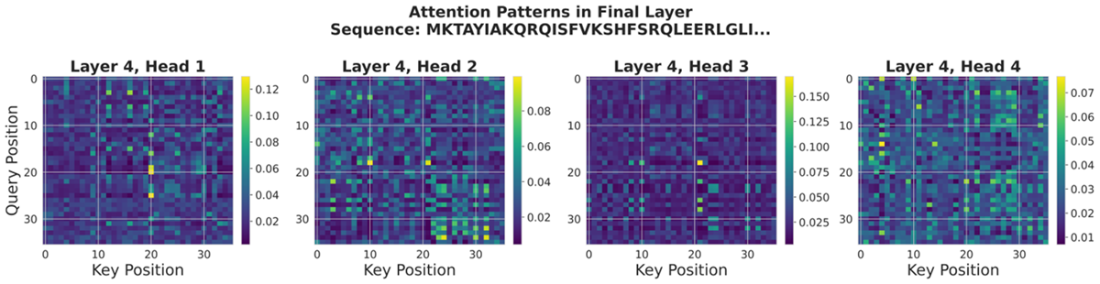
Inspect the four final-layer attention heatmaps to compare sink-like vertical stripes with local, distant, and diffuse attention patterns. section 12.3.3

