An attention weight is a normalized numerical coefficient showing how strongly an attention operation incorporates an associated value. In cross-attention, the decoder computes one weight for each encoder hidden state, based on its relevance to the current decoding step. section 12.3.1
Cross-attention uses the weights in a query-key-value workflow:
- The decoder’s current hidden state supplies the query. section 12.3.1
- Encoder hidden states supply the keys and values. section 12.3.1
- Comparisons produce attention weights, which determine each hidden state’s contribution to the weighted-sum context vector. section 12.3.1
Protein structure prediction
When predicting structure at output position j, the decoder may assign higher weights to nearby sequence positions or to distant positions that interact with j in three-dimensional space. section 12.3.1
Figure 12.8 The mechanics of cross-attention. A decoder state acts as a query (qj) and compares itself against all encoder states (keys, K). These comparisons generate attention weights (α), which are used to compute a weighted sum of the encoder states (values, V), creating a context vector (cj) specific to the current prediction step.
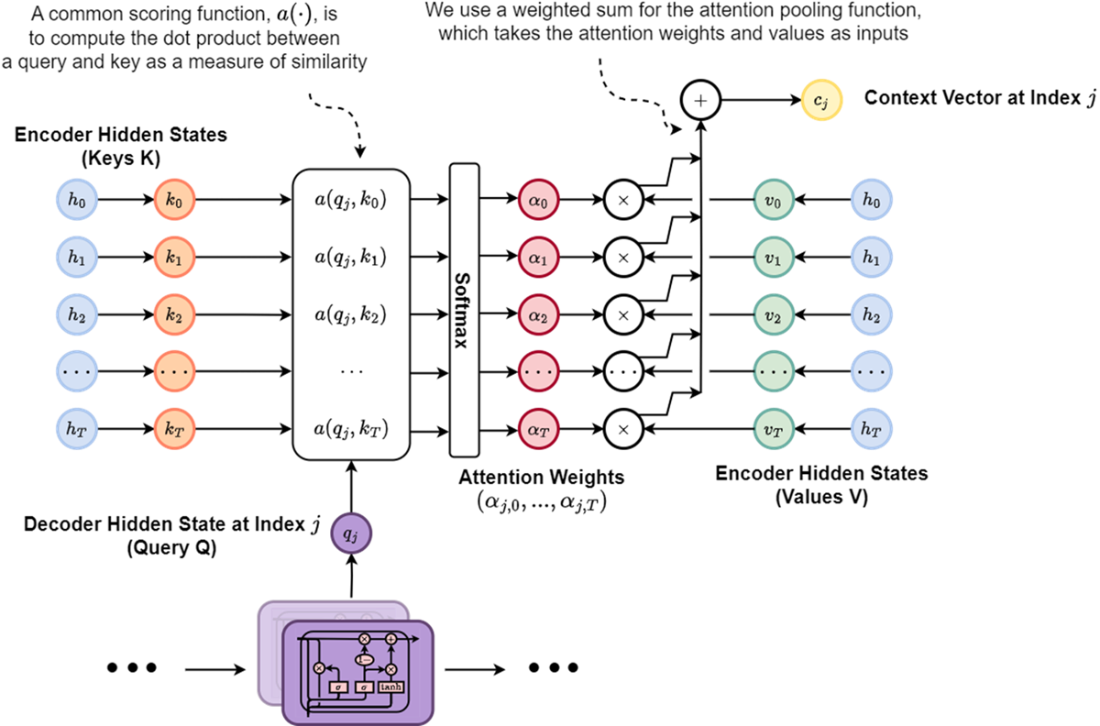
Shows how decoder queries compare with encoder keys to generate weights and a position-specific context vector. section 12.3.1






