Availability measures how cheaply and quickly you can obtain a signal for judging an agent’s output, without special infrastructure or human labor. It matters alongside precision: the most useful signal is the most precise one you can actually get for the task. section 2.2.1
Common signals trade availability against precision:
- Gold sets and human evaluation can be precise, but take time and effort to produce. section 2.2.1
- An LLM-as-Judge is widely available because it requires another model call, but its opinions can be less precise. section 2.2.1
- Unit tests and tool outcomes provide checks when a task has an executable pass/fail result. section 1.4.1
Figure 2.3 scatter plot demonstrating how precision and availability can guide your determination of how to evaluate good output from an agent
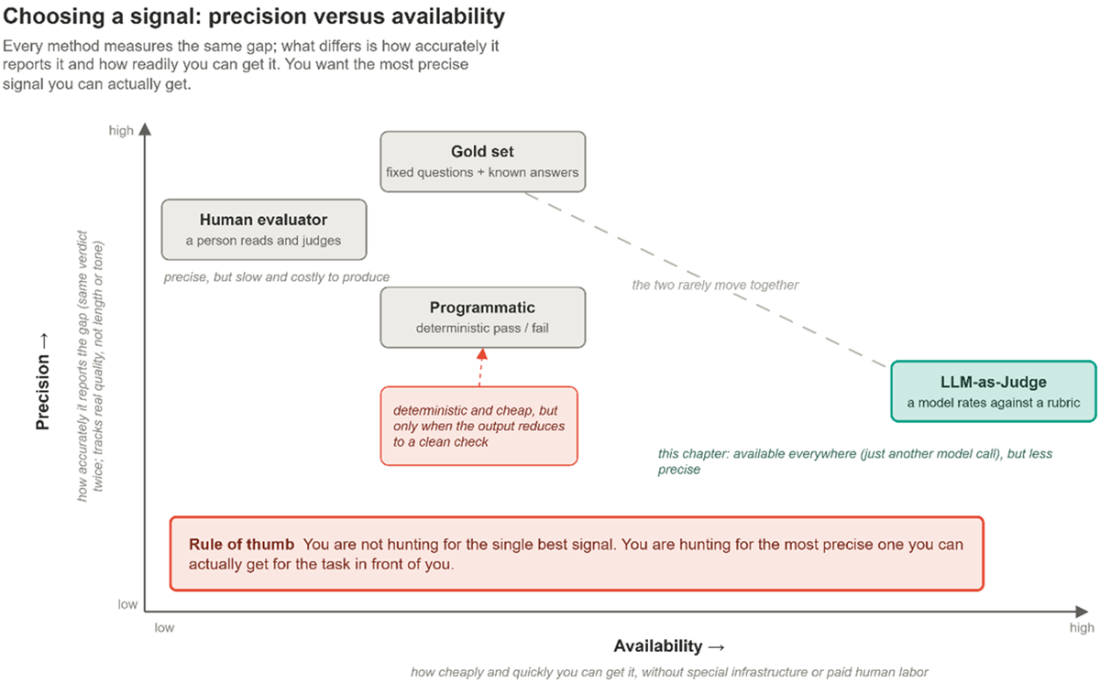
Use the precision–availability plot to compare candidate signals for evaluating agent output. section 2.2.1
