AVX-512 VNNI adds a fused INT8×INT8→INT32 dot-product instruction to x86, targeting the cost of quantized matrix multiplication in CPU inference. Its operation is the integer counterpart of a floating-point fused multiply-add. section 10.4
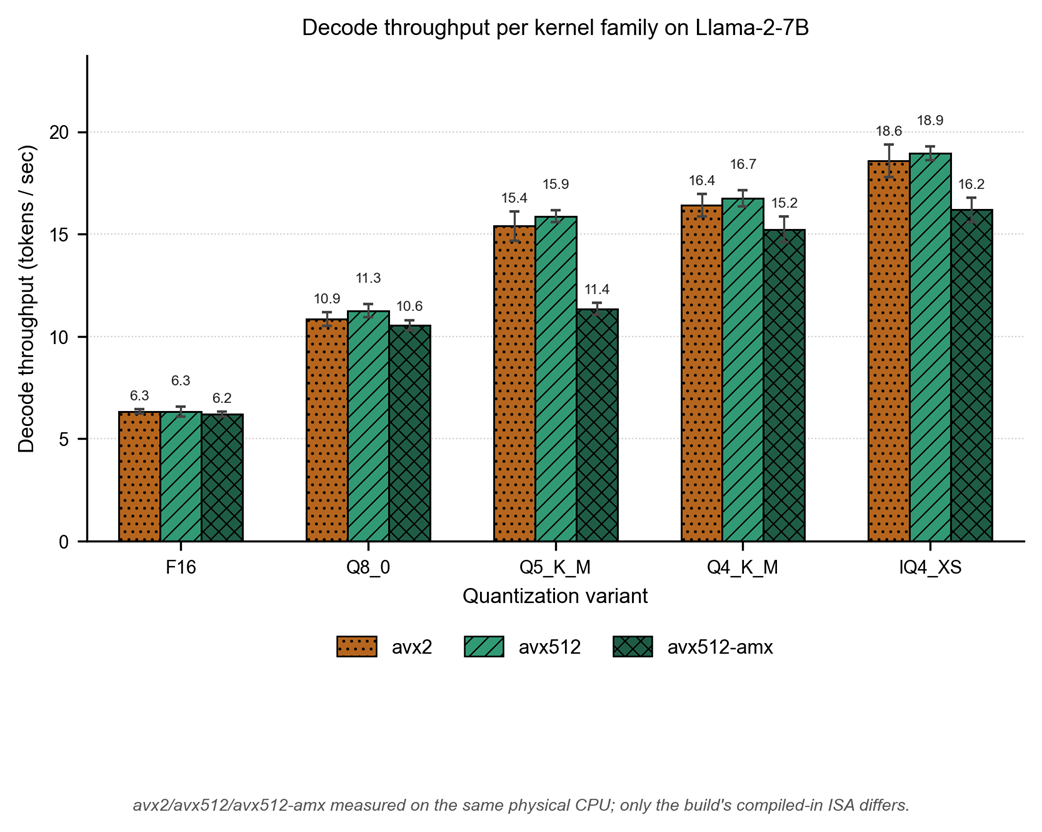
For single-token decode, wider vectors and faster integer dots can matter less than the rate at which weight data reaches the processor. On the measured workload, AVX-512 with VNNI improved integer-format throughput over AVX-2 by only 1.8–3.7%. section 10.4.3
Choose CPU kernels according to request shape:
- For single-stream decode on the measured Sapphire Rapids server, use AVX-512 with VNNI and leave AMX off; the AMX-enabled build regressed on every tested quantized format. section 10.4.5
- For prompt processing above roughly 256 input tokens, AMX can win; separate binaries routed by request shape are one deployment option. section 10.4.5
Decode throughput
On four tested integer formats, AVX-512 improved over AVX-2 by 1.8% for IQ4_XS, 2.0% for Q4_K_M, 3.0% for Q5_K_M, and 3.7% for Q8_0. section 10.4.3
Figure 10.9 Decode throughput on Llama-2-7B across five quantization formats and three llama.cpp builds. F16 is flat across all three builds because it does not enter any of the integer dot-product instructions the build flags govern; its column measures the host's memory bandwidth alone. The integer formats show single-digit-percent gains from AVX-512+VNNI over AVX-2 and consistent regressions on the AMX-enabled build. Q5_K_M's regression on AMX is roughly three times the regressions Q4_K_M and Q8_0 seen on the same build.
Compare decode throughput across quantization formats and CPU builds, including the measured AVX-512 and AMX tradeoffs. section 10.4.3
