A bandit algorithm learns while choosing: it selects an action, observes its immediate reward, and updates its strategy. Its central challenge is balancing exploration of uncertain options with exploitation of options that have performed well. section 5.1 section 5.7
Common decision strategies include:
- Epsilon-greedy explores occasionally while usually choosing the current favorite. section 5.7
- UCB directs exploration toward options with greater uncertainty. section 5.7
- Thompson Sampling uses a Bayesian approach to balance exploration and exploitation. section 5.7
Business decisions
Choosing among ads, emails, layouts, or discounts can use immediate rewards to improve decisions over time. Contextual bandits can use information such as demographics or time of day to personalize choices. section 5.7
Figure 5.1 Comparing multi-armed bandits, contextual bandits, and full reinforcement learning.
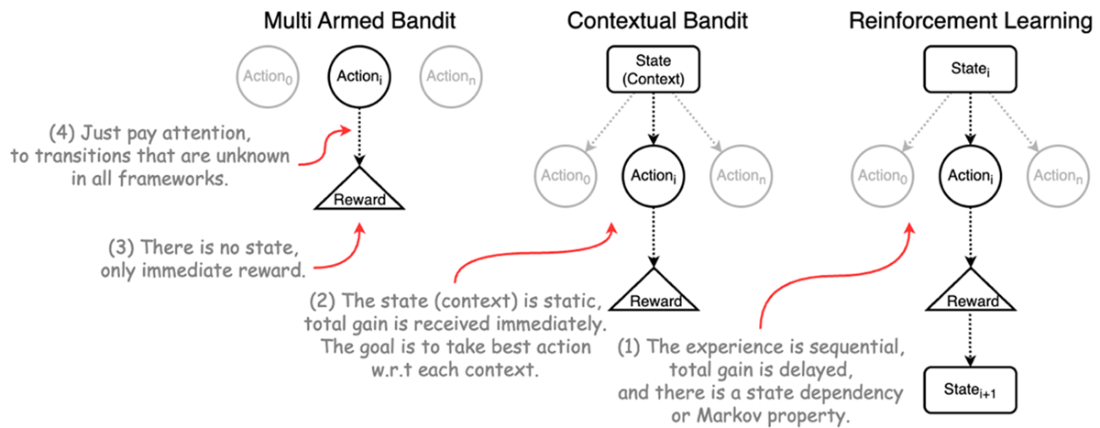
Compare multi-armed bandits, contextual bandits, and full reinforcement learning by the role of state and sequential planning. section 5.1
