BART is a Transformer sequence-to-sequence model that maps an input text sequence to a corresponding output, supporting tasks such as translation, summarization, and vignette generation. Its encoder-decoder structure makes it suitable for representing conditional text distributions rather than only completing text from an empty prompt. section 13.3.2
In a causal language model, fine-tuning aligns pretrained language generation with a causal Markov kernel. A BART model can generate a Prince’s action from a King’s action, generate a Kingdom’s fate from both actions, or infer a King’s action from a Prince’s action. Hugging Face Transformers supplies tokenization, pretrained weights, and sequence-to-sequence training utilities. section 13.3.2
Conditional story generation
Fine-tune separate BART models on paired King–Prince and action–fate vignettes, then generate a full story by passing each generated sequence to the next model. PyTorch and Seq2SeqTrainer support tokenization, validation splits, training, generation, and log-probability calculations. section 13.3.2
Figure 13.6 A BART sequence-to-sequence model is fine-tuned to represent the Prince’s action given the King’s action.
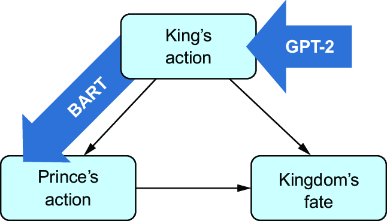
Shows BART mapping the King’s action vignette to the Prince’s action. section 13.3.2

