Batch ingestion loads data accumulated over a defined period—hourly, daily, or weekly—into a lakehouse in discrete processing runs. It favors throughput, reliability, predictable operations, and cost control when low latency is not essential. section 6.2.1
A practical batch pipeline typically follows these responsibilities:
- Extracts data from operational databases, flat files, or APIs. section 6.2.1
- Transforms and validates records before writing them as Parquet files to Iceberg tables. section 6.2.1
- Uses scheduled jobs or pipelines orchestrated with Apache Spark, dbt, or Airflow. section 6.2.1
- Writes through append, overwrite, or upsert operations; each batch creates an Iceberg snapshot with atomic commit behavior. section 6.2.1
Recovery is reliable only when each run reads a fixed snapshot or clearly scoped input chunk. Explicit boundaries make retries, historical backfills, reconciliations, and corrective processing safer; mutable, undefined inputs can cause retries to process different data and undermine idempotency. section 6.2 section 6.2.1
Choosing batch for reporting
A bank can run nightly batch jobs through Apache Spark and existing Airflow DAGs for compliance and financial reporting, while reserving streaming for latency-sensitive trading workloads. section 4.4.2
Figure 6.4 Ingesting data for the day, once a day, in a batch job
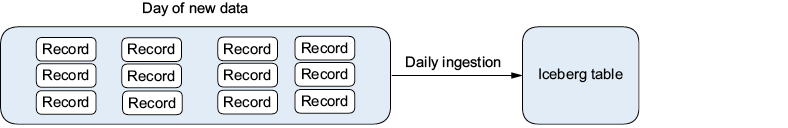
Visualizes a daily collection window followed by one scheduled ingestion run. section 6.2.1
