A behavior policy selects the actions an agent takes and generates the experience used for learning. In off-policy learning, it can differ from the target policy—the policy the updates aim to improve. section 6.3 section 6.4.2
Q-learning
An agent can use ε-greedy action selection to explore while Q-learning updates toward a greedy target. The experience comes from the behavior policy; the learning target describes what the agent would do if it chose the best action. section 6.4.2
Figure 6.6 Q-learning Algorithm Flowchart.
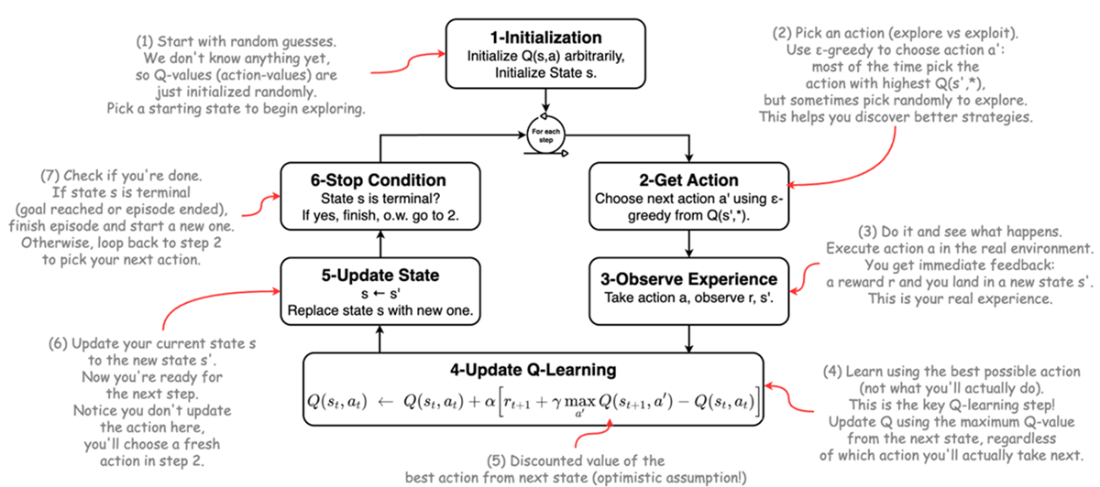
Follow the Q-learning flow to see where action selection generates experience and where the update uses the greedy target. section 6.4.2
