DualPipe is a pipeline-parallel training schedule designed to keep GPUs busy by overlapping work from different micro-batches. Its bidirectional form runs two data streams at once and schedules forward and backward computations alongside communication. section 6.5.5 section 6.5.6
The schedule addresses a bottleneck left by 1F1B: alternating forward and backward passes reduces pipeline bubbles, but mixture-of-experts (MoE) layers still need expensive all-to-all exchanges to send tokens to experts on different GPUs. GPUs can otherwise wait for those exchanges even when the pipeline is balanced. section 6.5.4 section 6.5.5
DualPipe creates opportunities for overlap at two levels:
- Fold the pipeline so that each GPU holds an early stage and a non-contiguous late stage. This layout enables more flexible scheduling than assigning one sequential slice to each GPU. section 6.5.5
- Break passes into finer operations, including attention, expert computation, and all-to-all communication. Schedule communication for one micro-batch alongside useful computation for another; forward and backward work can also overlap. section 6.5.6 section 1.2.2
Figure 6.8 The DualPipe schedule with fine-grained overlap. This diagram shows how forward, backward, and overlapped tasks are scheduled to keep the GPUs constantly busy and hide communication latency.
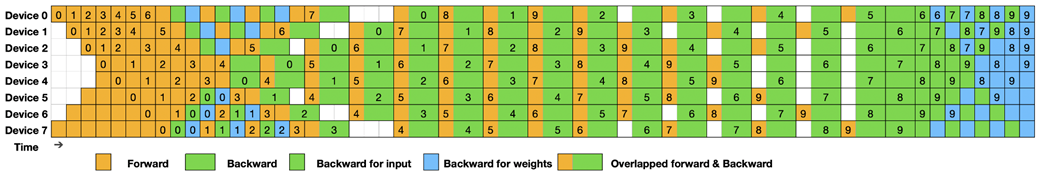
The timeline shows how forward, backward, and overlapping tasks are arranged to hide communication latency. section 6.5.6
A folded layout on four GPUs
For eight stages on four ranks, assign stages 0 and 7 to rank 0, stages 1 and 6 to rank 1, stages 2 and 5 to rank 2, and stages 3 and 4 to rank 3. This placement illustrates folding; the V-shaped DualPipeV variant uses a simpler data flow than the two-stream bidirectional schedule. section 6.5.5 section 6.5.6
The gain is reduced communication-related idle time, not free parallelism. The folded DualPipe and DualPipeV approach increases parameter memory per GPU, with a stated cost of twice the parameter memory. section 6.5.8 section 6.6
