liveBook · Manning

Binary attention bias

As explained in Time Series Forecasting Using Foundation Models

A binary attention bias is a learned additive bias that distinguishes attention between positions from the same variate and positions from different variates.

A binary attention bias is a learned additive bias that tells attention whether two positions belong to the same variate or to different variates. It supports flattening multivariate inputs into one sequence without losing series identity. section 6.1.1

The mechanism separates relationships using variate indices:

  • For matching indices, the model adds the learnable same-variate parameter u(1). section 6.1.1
  • For different indices, the model adds the learnable cross-variate parameter u(2). section 6.1.1
  • This lets attention distinguish historical values from a target series and information from other series or exogenous features. section 6.1.1
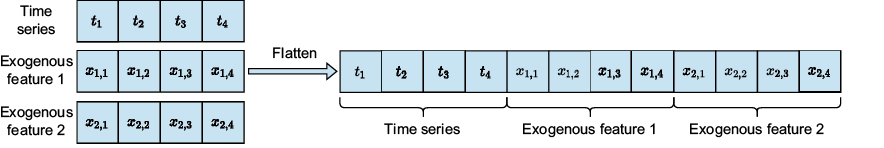
Figure 6.3 To handle an arbitrary number of variates, Moirai flattens the data into a single series.
A line of black text

Description automatically generated with medium confidence

The flattening diagram shows why series identity must be encoded after multiple variates become one sequence. section 6.1.1

How Time Series Forecasting Using Foundation Models covers it

How deep it goes
Defines the additive mechanism and parameter choices, but does not provide the displayed equation’s full notation or implementation code.
Examples
Uses a flattened target series with two exogenous features and contrasts attention within and across variates.
What you can do after
Evaluate/understand how attention can handle arbitrary numbers of series and exogenous features.
How it connects
Connects multivariate forecasting with attention mechanisms, transformers, exogenous features, and sequence flattening.

This explainer was generated by Manning's knowledge graph from the text of Time Series Forecasting Using Foundation Models. The section links point to the parts of the book it draws on.