BitNet b1.58 2B4T is a 2-billion-parameter language model trained on 4 trillion tokens with ternary weights {−1, 0, +1}. Its 1.58-bit format is trained into the model: weights are quantized during each forward pass, while a straight-through estimator sends gradients to full-precision master weights. This lets training adapt to ternary rounding rather than imposing it after training. section 8.5.2 section 8.5.3
On WikiText-2, it reaches 20.27 perplexity and uses 0.45 GB in packed form; OPT-2.7B measures 19.22 perplexity and 5.18 GB. The perplexities are only approximate comparisons because the models use different tokenizers. bitnet.cpp runs the packed model on CPU using addition and subtraction, without a GPU. section 8.5.3
Figure 8.20 BitNet b1.58 2B4T vs OPT-2.7B. Left: model storage. The BF16 master weights (middle bar, 4.49 GB) are what HuggingFace transformers loads for correct inference. The packed format (right bar, 0.45 GB) is what bitnet.cpp deploys. Right: WikiText-2 perplexity is comparable across models despite different tokenizers (19.22 vs 20.27).
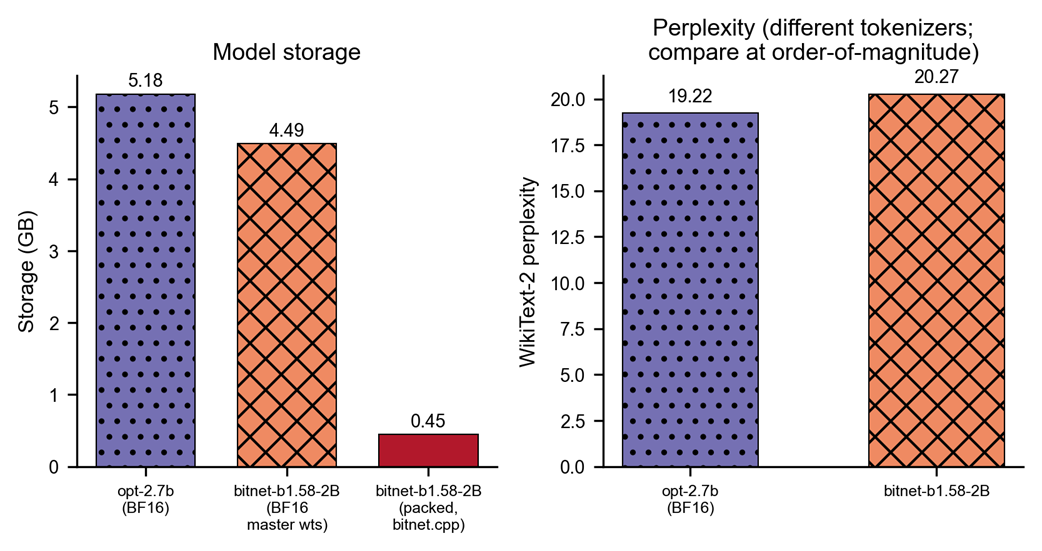
Compare packed and BF16 storage with WikiText-2 perplexity for BitNet b1.58 2B4T and OPT-2.7B. section 8.5.3
