Boot time is the elapsed time a machine or service instance needs to start and become ready. For LLM services, loading a large compiled model into GPU memory can make startup painfully slow, so storage strategy becomes an operational decision. section 6.1.2
Common storage choices involve different trade-offs:
- Object storage such as cloud buckets offers inexpensive storage, replication, fault tolerance, and high availability, but retrieving large models can be slow because assets are distributed across machines. section 6.1.2
- Fusing mounts a bucket like an external hard drive, simplifying loading code and avoiding a separate download step, but still retrieves model objects across machines and can remain slow. section 6.1.2
Figure 6.3 Different strategies for storing LLMs and their implications at boot time. Often, we have to balance system reliability, complexity, and application load time.
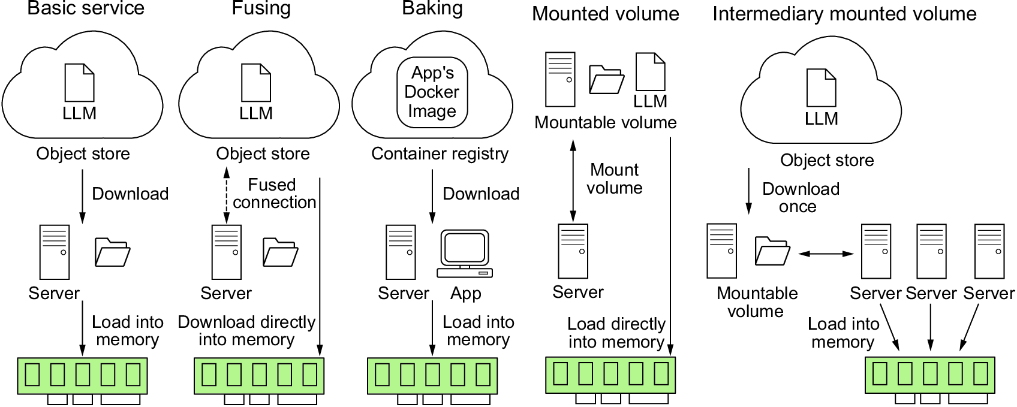
Compare LLM storage strategies by reliability, complexity, and application load time. section 6.1.2
