Bootstrap sampling creates data-set replicates by drawing observations at random with replacement. A replicate can match the original sample size while containing repeated observations and omitting others. Those small differences let the same learning algorithm produce diverse fitted models from one training set. section 2.2.1 section 2.2
To form and use bootstrap samples in a bagging workflow:
- Choose the number of observations to draw for each replicate; it may equal the original training-set size. section 2.2.1 section 2.2.2
- Draw observations with replacement, so an observation can occur several times while another is not drawn at all. section 2.2.1
- Fit one base estimator independently on each replicate; differing repetition patterns produce somewhat different estimators. section 2.2.1 section 2.2.2
- Aggregate estimator predictions: use majority voting for classification and a mean for regression. section 2.2 section 7.2.1
Figure 2.3 Bootstrap sampling illustrated on a data set of six examples. By sampling with replacement, we can get a bootstrap sample size of six, containing only four unique objects but with repeats. Performing bootstrap sampling several times produces several replicates of the original data set—all of them with repeats.
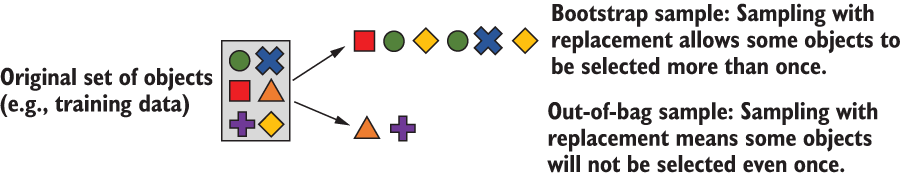
A six-observation example makes replacement visible: a same-size bootstrap sample can contain only four unique observations because some are repeated. section 2.2.1
Observations never selected for a particular replicate form its out-of-bag (OOB) sample. Because that estimator did not train on them, these held-out observations can evaluate the ensemble and yield an OOB error or score without a separate validation set or cross-validation. section 2.2.1
Bagging decision trees
Generate a bootstrap index array with NumPy, fit a decision tree on the indexed rows, and repeat for many trees. On noisy two-dimensional moon-shaped data, 500 depth-12 trees trained on bootstrap samples of 300 observations achieved 89.90% test accuracy, compared with 83.84% for one tree. Aggregation smooths individual overfitting and sensitivity to outliers, although training every full estimator can be costly. section 2.2.2 section 7.2.1
Bootstrap sampling distinguishes bagging from pasting, which samples training examples without replacement. It also underlies random forests, where randomized decision trees add feature-level randomness; Extra Trees instead relies on stronger tree randomization and does not use bootstrap sampling. Bagging is especially useful with unstable, complex, or nonlinear estimators because aggregation reduces variability and smooths predictions. section 2.6 section 2.3




