A parent document is a larger text segment that contains smaller child documents. It preserves retrieval context while allowing embeddings to target precise child chunks. section 3.2
Build the structure as a staged retrieval pipeline:
- Split source text at structural boundaries such as numbered sections, then divide sections into parent chunks of up to 2,000 characters. section 3.2
- Split each parent into 500-character children, embed the children, and connect PDF, parent, and child nodes with graph relationships. section 3.2
- Search child embeddings, group matches by parent, retain each parent’s strongest score, and return the final k unique parents. section 3.2.1
Figure 3.4 Parent document graph representation
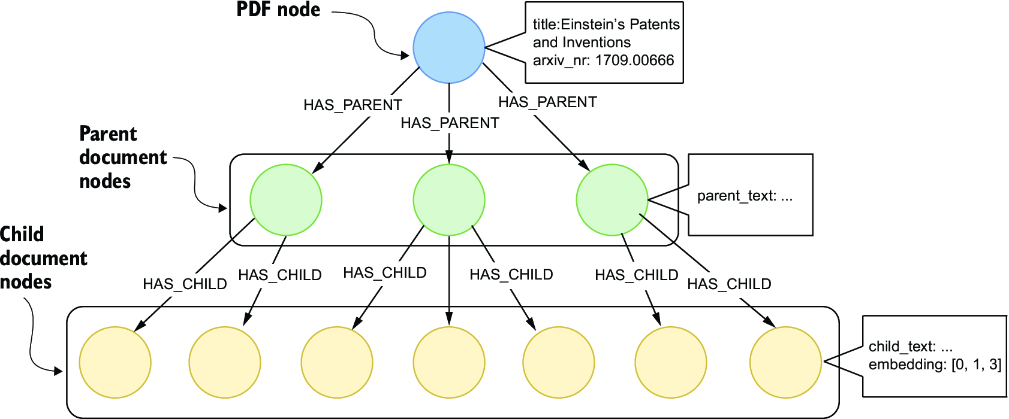
Use the graph representation to inspect how a PDF connects to parent nodes and their embedded child chunks. section 3.2
