A ScaledObject is a KEDA custom resource that creates a Kubernetes Horizontal Pod Autoscaler (HPA) and adds scaling features for workload triggers. It is especially useful when scaling from zero depends on traffic or queue metrics rather than CPU, memory, or GPU resource metrics. section 6.2.2
GPU-aware inference scaling
A production inference service can collect GPU utilization through NVIDIA DCGM, send it to Prometheus Operator, expose it through KEDA's custom metrics API, and use a ScaledObject to drive HPA replica changes. This adds observability and integration work beyond the built-in CPU and memory HPA. section 6.2.2
Configure it with care because LLM services have unusually slow and costly scaling behavior:
- Allow for GPU initialization and model-weight loading before expecting new replicas to serve requests. section 6.2.2
- Avoid aggressive scale-down, which can terminate instances before assigned tasks finish, and prevent flapping caused by unstable thresholds or policies. section 6.2.2
Figure 6.7 Autoscaling based on a custom metric like GPU utilization requires several extra tools to work, including NVIDIA’s DCGM, a monitoring system like Prometheus Operator, and a custom metrics API like that provided by KEDA.
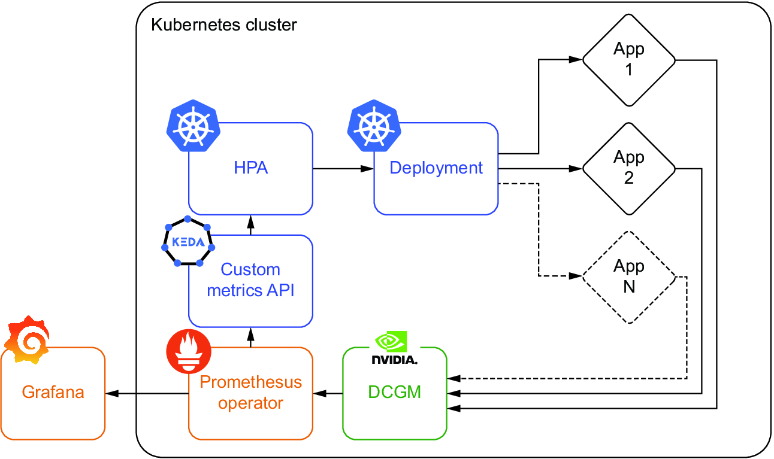
Use the architecture diagram to trace how DCGM, Prometheus Operator, KEDA, and the custom metrics API cooperate for GPU-based autoscaling. section 6.2.2
