A clipped policy ratio is a GRPO update constraint that limits how far the current policy’s probability ratio can move from a previous policy for the same sampled response. section 7.4 section 7.4.1
It compares old and new sequence logprobs for the same prompt and response, then clamps the ratio so a single update cannot change behavior too abruptly. section 7.4.1 section 7.5
The implementation uses this pattern:
- Copy the current model as a reference policy and sample fixed rollouts from it. section 7.4.2
- Compute old_logps from the reference policy and new_logps from the updated model on the same responses. section 7.4.1
- Form ratio from the logprob difference, clamp it to a bounded range, and use the minimum of unclipped and clipped objectives in the loss. section 7.4.1 section 7.4.1
Training workflow
One described workflow keeps a large rollout pool fixed, processes it in minibatches, then refreshes the reference model. A smaller approximation repeats the same logic on fresh batches during each step. section 7.4.2
Figure 7.10 We have plotted basic and advanced GRPO training metrics. Now we’ll modify the GRPO algorithm to add clipped policy ratios.
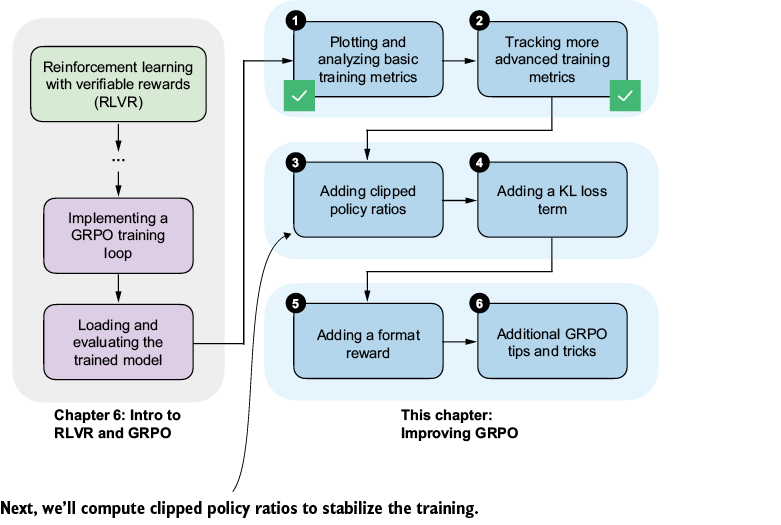
Figure 7.10 situates clipped policy ratios as the next GRPO modification after basic metrics analysis. section 7.4
