Combined retrieval handles questions that span multiple data sources by using a knowledge graph to resolve entities or relationships, then using that context to retrieve relevant documents. The knowledge-graph and document contexts are merged before answer generation. section 13.4.3
A practical retrieval pipeline can proceed as follows:
- Split the question into a knowledge-graph retrieval task and a document-retrieval task. section 13.4.3
- Use graph entities or relationships to constrain document selection, reducing failures from missing titles and irrelevant semantic matches. section 13.4.3
- Merge graph and document contexts, with semantic vector search available as a backup when the other retrievers return insufficient context. section 13.4.3
Cross-source identity resolution
For “What are this year’s transactions of the head of criminal group X?”, the knowledge graph identifies the person holding that relationship, and the financial-document search uses the person’s name to retrieve supporting records. section 13.4.3
Figure 13.4 KG-powered RAG agent with a grounding in external data sources: the KG and a vector database
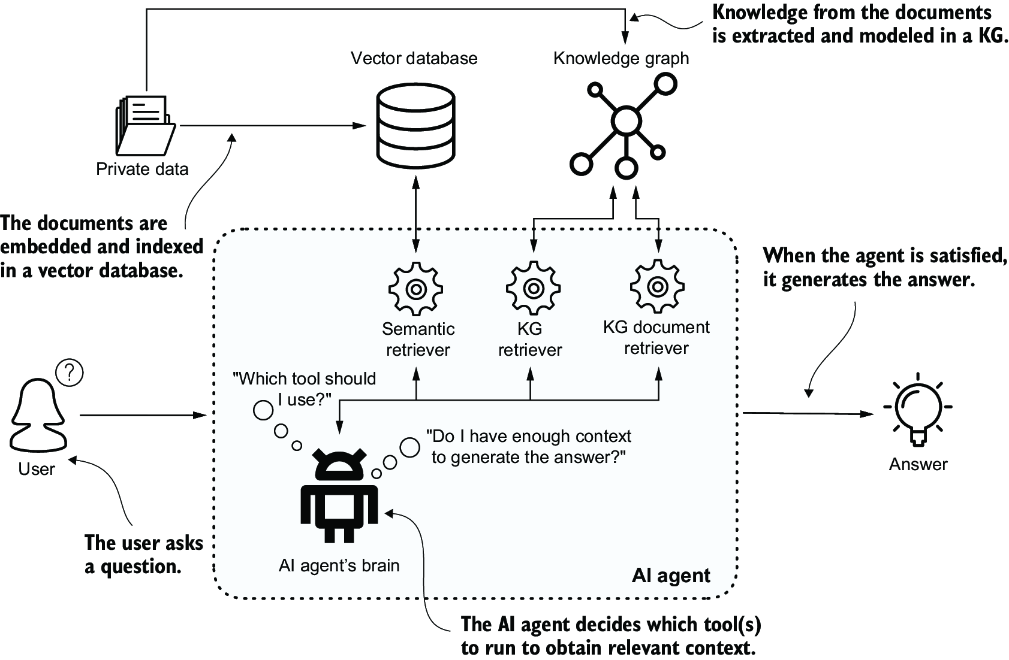
The architecture shows a grounded RAG agent combining a knowledge graph with a vector database as external data sources. section 13.4.3
