A compute-unit hint sets the ceiling on processors Core ML may consider; it does not pin individual operations to a processor. On Apple silicon, choosing this dispatch set can matter more than changing the weight format. section 11.3.1 section 11.6
The four settings define which compute units are available to the runtime:
- cpuOnly forces every operation onto the CPU. section 11.3.1
- cpuAndGPU permits Metal kernels but excludes the Neural Engine. section 11.3.1
- cpuAndNeuralEngine permits eligible operations on the Neural Engine and falls back to the CPU for the rest. section 11.3.1
- all lets the runtime choose across CPU, GPU, and Neural Engine. section 11.3.1
The hint cannot make unsupported operations run on the Neural Engine. If an operation falls outside its supported-op table, Core ML can silently route it to the GPU—even with cpuAndNeuralEngine selected. Check per-operation routing in an Xcode Performance Report or load an MLComputePlan with coremltools. section 11.3.2
Figure 11.8 EfficientNet-Lite0 p50 latency on Core ML, five variants (fp16, int8_linear, int8_weight_only, palettize_4bit, palettize_6bit) across four M3 compute-unit hints plus iPhone 16 all (the only mode Xcode Performance Reports expose). The cpuAndNeuralEngine and all columns on M3 land roughly 6× faster than the cpuOnly column on fp16 and roughly 7× faster on int8_linear. Inside the cpuAndNeuralEngine column the five variants collapse to within 0.1 ms of each other, because the Neural Engine quantizes activations internally and reads any compatible weight format at the same throughput.
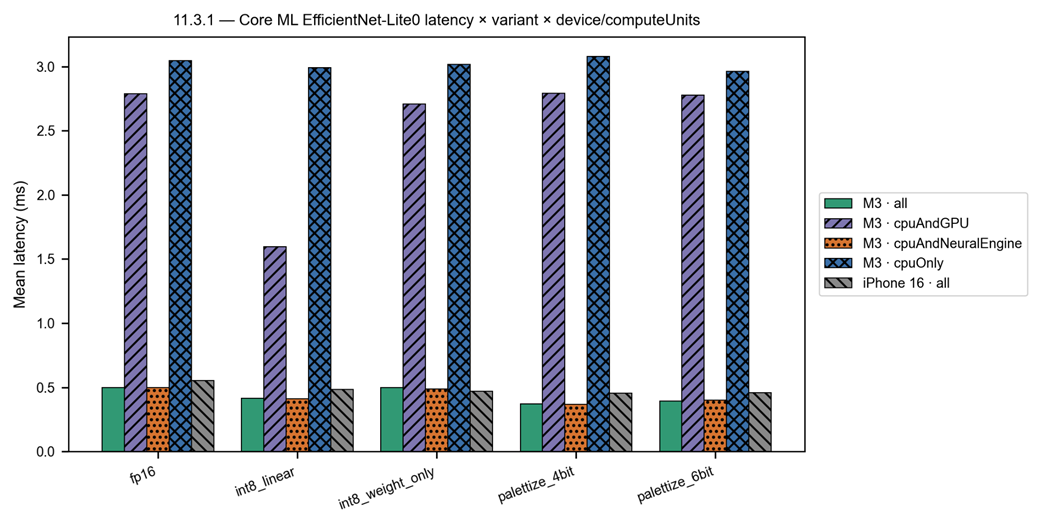
Compare EfficientNet-Lite0 latency across compute-unit settings and weight variants: Neural Engine routing is roughly six to seven times faster than cpuOnly in the cited M3 measurements, while variants within the Neural Engine setting differ by at most 0.1 ms. section 11.3.1
Unsupported operations can erase the expected benefit
Llama-3.2-1B has zero Neural Engine coverage in the cited iPhone 16 measurements and routes entirely to the GPU, even with all selected. Changing its weight quantization does not change that routing. section 11.3.2
