A conditional diffusion model is a text-to-image generator that learns to repair a noisy image using a caption as guidance. It starts from corrupted data during training, then reuses the same repair behavior to let an image emerge from random noise at inference time. section 1.32
The core setup is simple: a U-Net-style CNN receives a noisy image plus a text embedding. The text signal is inserted as an extra input channel, and the network is trained to reconstruct the clean image that matches the caption. section 1.32
The treatment breaks the idea into a practical workflow:
- Build training pairs from a clean image, an automatically corrupted version, and a manually written caption. section 1.32
- Feed the noisy image and caption embedding into the CNN so the caption steers the repair. section 1.32
- Repeat the repair step on random noise until a recognizable image appears. section 1.32
Image generation from a prompt
A totally random, TV-static-like image is paired with the desired caption. The model repeatedly improves that image until the target object becomes visible. section 1.32
Figure 1.11 A diffusion model is trained to improve a corrupted image paired with its caption.
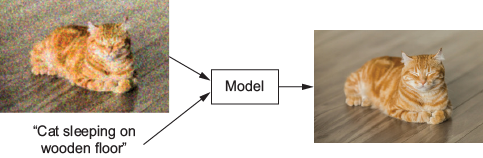
Shows the training view: a corrupted image paired with its caption. section 1.32
Figure 1.12 A diffusion model is used repeatedly to have a desired image emerge from Gaussian noise.
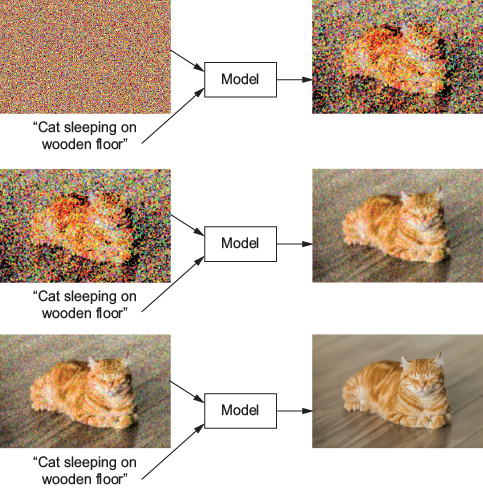
Shows the generation view: repeated denoising from Gaussian noise. section 1.32
