Conditioning information is auxiliary input supplied to a generative process to influence its output. In diffusion models, it can be a class label or text prompt that steers image generation toward a desired concept. section 6.1.1
Classifier-free guidance uses conditioning in three stages:
- Train the diffusion model both with conditioning and without it, allowing conditional and unconstrained generation. section 6.1.1
- During inference, combine the model’s conditional and unconditional predictions to steer partially denoised samples. section 6.1.1
- Adjust the CFG scale to trade adherence to the condition against output diversity: higher values strengthen alignment, while lower values preserve creativity. section 6.1.1
Prompt-guided image generation
A text prompt supplies conditioning information to a diffusion model. Class labels work similarly, while the model’s unconditional prediction provides a reference for controlling how strongly the requested concept shapes the image. section 6.1.1
Figure 1.10 The eight steps to building a text-to-image generator from scratch
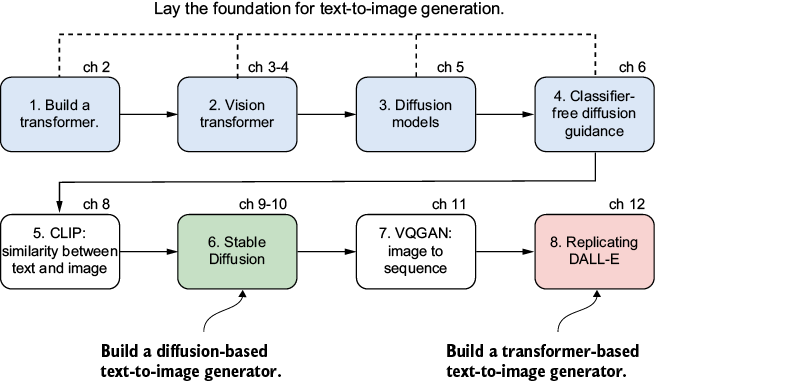
Use the eight-step roadmap to locate conditioning after basic diffusion and before CLIP-guided text-to-image generation. section 1.4

