liveBook · Manning

Cubin

As explained in GPU Programming with Triton

A cubin is a CUDA binary containing GPU machine code compiled for a particular NVIDIA GPU architecture.

A cubin is a GPU binary containing the instructions executed when a Triton kernel runs. NVIDIA’s assembler produces it from PTX, the final step in Triton’s compilation pipeline. section 2.3.1

The first call to a Triton kernel triggers compilation on the CPU. Triton caches the resulting binary, so later calls with the same argument types and constexpr values skip compilation. Discard the first call—and usually several warmup calls—when measuring steady-state execution. section 2.2.10

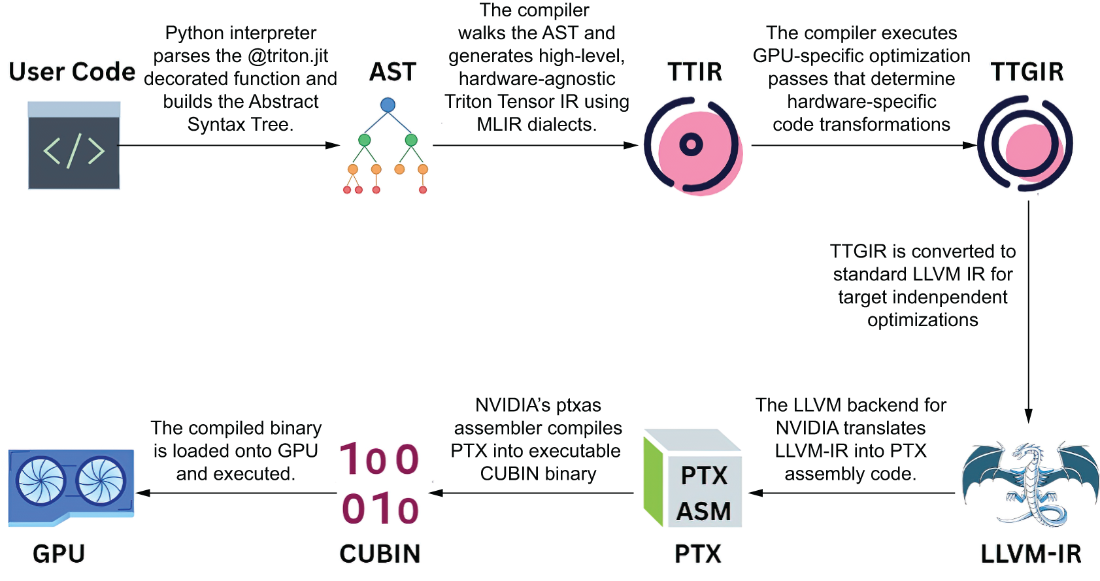
Figure 2.10 The Triton compiler pipeline: from user code through AST, TTIR, and TTGIR to GPU execution via LLVM-IR, PTX, and CUBIN.
CH02 F10 Fartale

Follow the pipeline from Triton source through intermediate representations and PTX to GPU execution via cubin. section 2.3.1

How GPU Programming with Triton covers it

How deep it goes
Traces compilation from LLVM IR through NVIDIA PTX to assembled GPU instructions, without detailing cubin format internals.
Examples
Uses a Triton vector-add kernel to illustrate first-call cubin compilation, cached reuse, and warmup before timing.
What you can do after
Understand why first-call timing includes CPU-side compilation and why warmup runs isolate steady-state GPU execution.
How it connects
Connects Triton compilation with LLVM IR, PTX, NVIDIA's assembler, CUDA, and GPU kernel launch.

Related concepts

This explainer was generated by Manning's knowledge graph from the text of GPU Programming with Triton. The section links point to the parts of the book it draws on.