A content path separates semantic attention from positional attention. It derives query, key, and value representations from token content alone, keeping RoPE out of the MLA stream so the absorption trick remains available. section 3.14 section 3.14.1
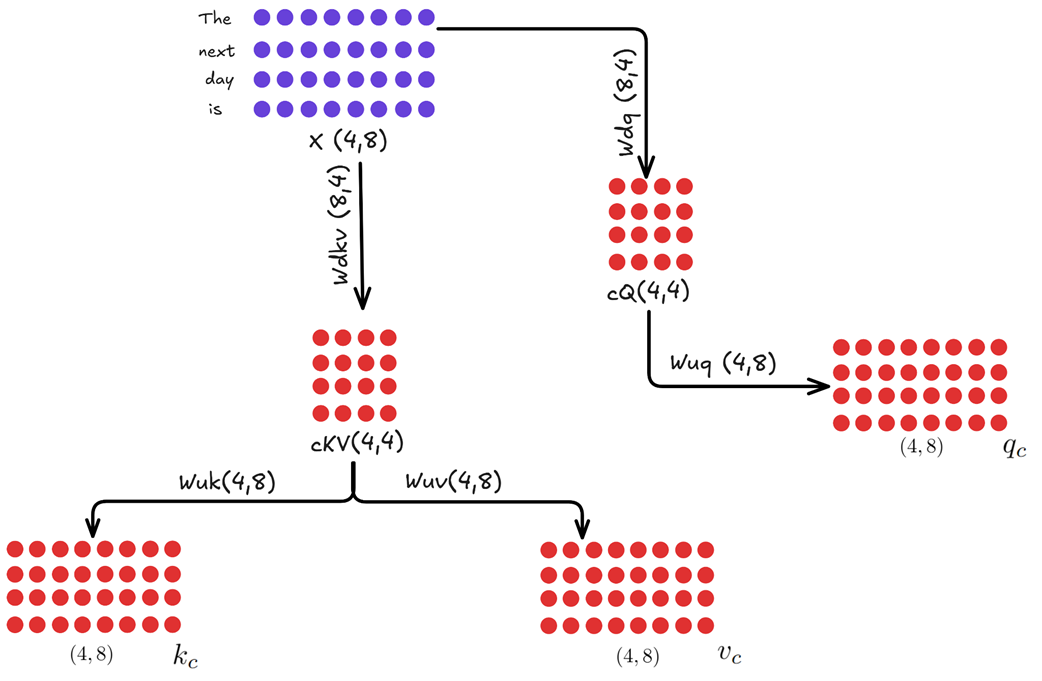
Build the content path through the pure MLA projection sequence:
- Down-project the input X into a latent query cQ and latent key-value representation cKV. section 3.14.1
- Up-project the latent representations to form Qc, Kc, and Vc: Qc = (X × Wdq) × Wuq, Kc = (X × Wdkv) × Wuk, and Vc = (X × Wdkv) × Wuv. section 3.14.1
- Compute content scores from Qc × Kcᵀ, cache cKV, and use Vc to form the later context vector. section 3.14.1 section 3.16
Autoregressive update for “bright”
When “bright” arrives after “The next day is,” down-project its embedding into a latent vector and append it to the latent KV cache. An absorbed content query then scores the updated cache without recomputing full historical key and value representations. section 3.14.4
Figure 3.28 The Content Path of the Decoupled Architecture. This is a standard MLA block that produces content-based Query (Qc), Key (Kc), and Value (Vc) matrices.
Trace the parallel architecture visually: the content path produces Qc, Kc, and Vc, while a separate position path contributes RoPE-based positional scores. section 3.14.1
