Fine-grained expert segmentation addresses knowledge hybridity in mixture-of-experts models. Instead of using a few large experts that each become generalists, it routes tokens through a much larger pool of smaller, more specialized experts. section 4.4.2
Capacity-preserving segmentation
A conventional MoE with 16 experts of hidden dimension 4096 has aggregate expert capacity of 16 × 4096. A fine-grained design can use 64 experts of hidden dimension 1024, preserving 64 × 1024 = 16 × 4096 while giving routing a wider specialization pool. Total expert parameters, activated top-k parameters, and inference cost can remain unchanged. section 4.4.2
Figure 4.20 A comparison between a conventional MoE with a few large experts (top) and DeepSeek's fine-grained approach with many smaller experts (bottom).
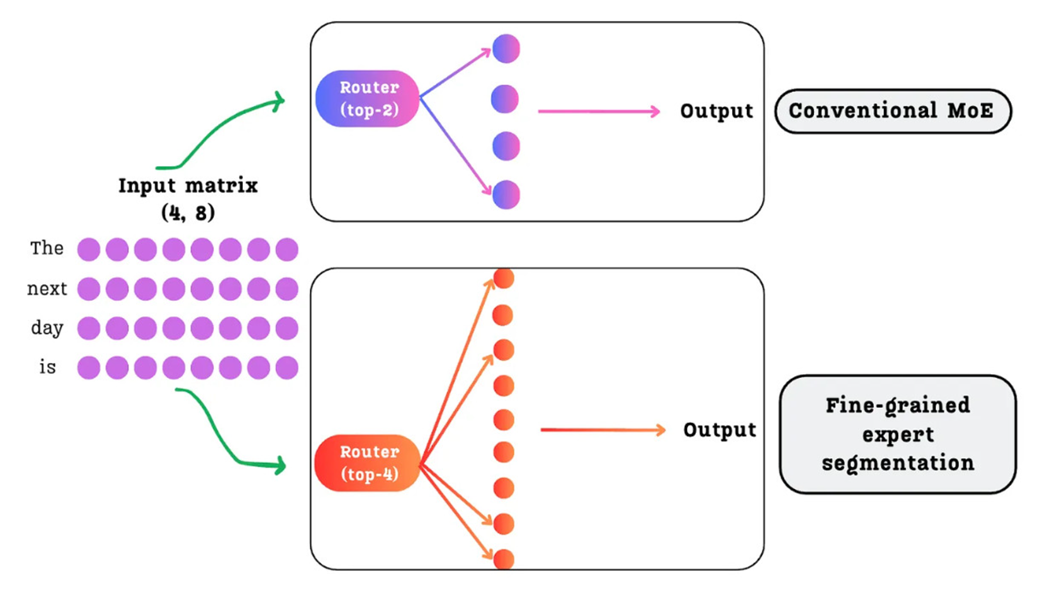
Compare few large experts with many smaller experts to see how segmentation preserves aggregate capacity while enabling finer specialization. section 4.4.2
