Standard MoE is a baseline mixture-of-experts architecture that uses a conventional auxiliary load-balancing loss. A matched training comparison configured it with approximately 101.30 million parameters. section 4.6
The empirical comparison highlights:
- Training on TinyStories for 5,000 iterations produced a best validation loss of 1.9854. section 4.6
- The baseline required 14.29 minutes and reached 350.0 iterations per minute. section 4.6
- Expert-selection frequencies were uneven in a sample batch, revealing imbalanced routing. section 4.6
Figure 4.29 Expert selection frequency for the Standard-MoE model in a sample batch. The uneven distribution highlights the problem of imbalanced routing.
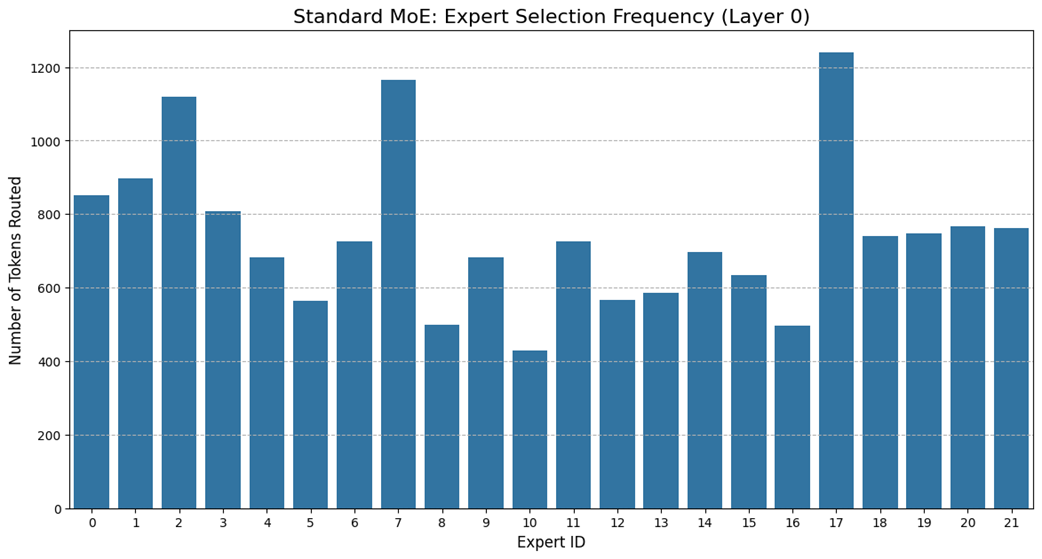
The expert-selection frequency plot makes the baseline’s uneven routing visible and provides a direct contrast with dynamic balancing. section 4.6
Matched comparison
Against DeepSeek-MoE, Standard MoE achieved a best validation loss of 1.9854, compared with 1.9451, while training more slowly and reaching lower throughput. section 4.6
