DataDriftPreset generates an Evidently report that compares every column in reference and current datasets, helping monitor distributional changes in production ML data. section 6.2.1
The generated report provides:
- Reference and current distributions for each feature. section 6.2.1
- The statistical test used, plus its drift score or p-value. section 6.2.1
- A default Wasserstein-distance threshold of 0.1 for classifying drift. section 6.2.1
Generate and save a report
Define Report(metrics=[DataDriftPreset()]), run it with reference_data and current_data, then save the result with report.save_html("drift_report.html"). section 6.2.1
Figure 6.16 An example of an Evidently data drift report. The panel provides quick information about the number of drifted columns and missing values in the current and reference datasets.
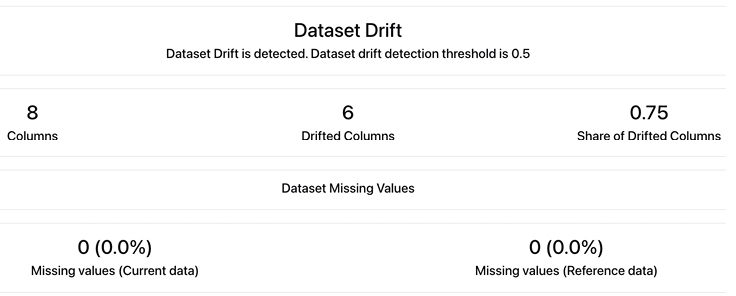
Use the report view to scan drifted columns and missing values across the two datasets. section 6.2.1
