A data engineer builds and operates the data foundation for machine learning: collecting source data, transforming and enriching it, labeling examples, and continuously ingesting processed data. section 1.1.2
In a machine-learning development workflow, the role includes:
- Collecting data from sources such as user activity logs and customer surveys. section 2.2.2
- Transforming, enriching, and labeling data for training datasets. section 1.1.2
- Operating ingestion workflows that append new records and support dataset status queries. section 2.2.2
- Collaborating with data scientists who fetch prepared datasets for model training. section 2.2.2
A practical dataset-management service separates responsibilities into a data ingestion layer, internal dataset storage, and a dataset fetching layer. The ingestion interface receives and tracks training data; the fetching interface supplies datasets to training code. section 2.2.2
Training-data workflow
A data engineer parses user activity logs and collects customer surveys, labels the resulting examples, creates or updates a dataset through an ingestion API, and monitors its status. Training code then fetches the dataset for an intent-classification model. section 2.2.2
Figure 2.6 System overview of the sample dataset management service. The sample service contains three main components, a data ingestion API, internal storage, and a dataset fetching API.
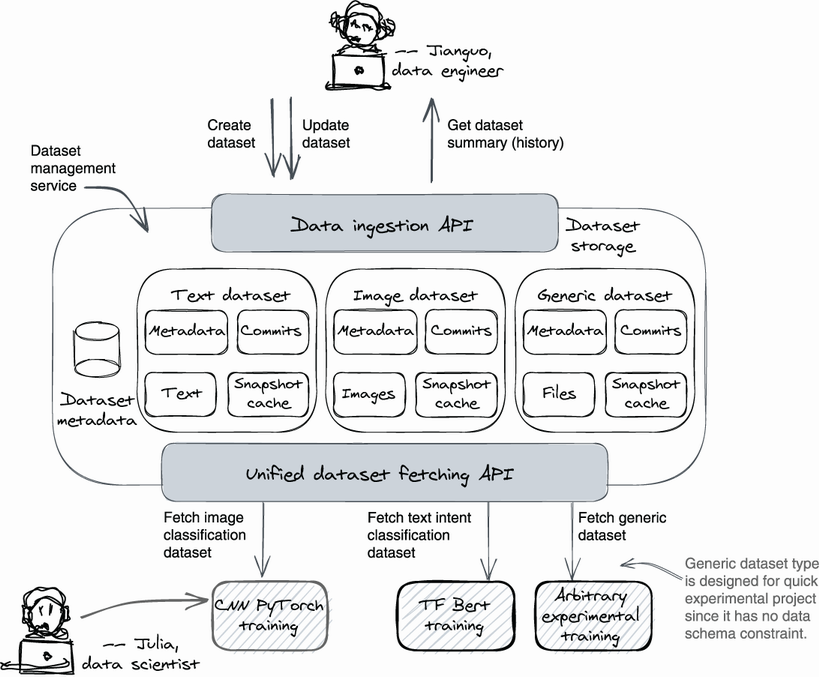
Use the system overview to trace how ingestion, internal storage, and dataset fetching support separate producer and consumer interfaces. section 2.2.2


