A Delta table stores batch or streaming data in cloud object storage while adding transaction-log metadata, schema enforcement, indexing, caching, ACID transactions, and table history. It behaves like a SQL table: query, insert, update, and merge operations are supported. section 2.3.1
A production data pipeline commonly separates responsibilities across:
- Bronze tables retain raw input. section 2.3.1
- Silver tables apply cleaning and transformation. section 2.3.1
- Gold tables hold filtered and purified data for downstream use. section 2.3.1
Reading a historical version
Use DeltaTable.forPath(spark, pathToTable) to inspect history, then read a prior state with format("delta"), timestampAsOf, or versionAsOf. section 2.3.1
Figure 2.16 Delta Lake data ingestion and processing workflow. Both stream data and batch data can be saved as Delta Lake tables, and the Delta Lake tables are stored in the cloud object storage, such as Amazon S3.
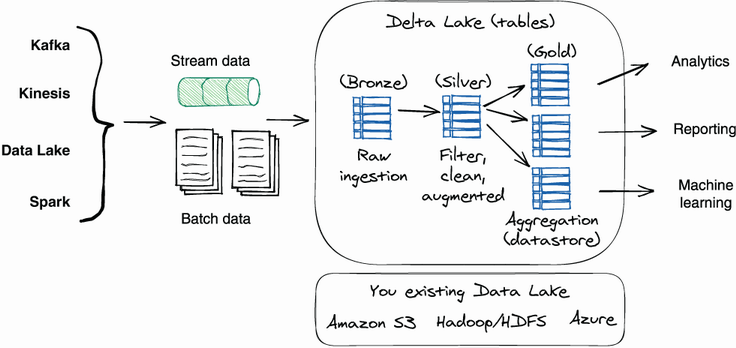
Shows how batch and streaming inputs become Delta tables in cloud object storage and flow through processing stages. section 2.3.1
