liveBook · Manning

Discount factor

As explained in Applied Reinforcement Learning

A numerical factor that determines how strongly future rewards and values are weighted relative to immediate rewards.

In a Bellman equation, the discount factor γ scales the expected value of the next state when calculating a state's value. It controls how far into the future the calculation looks. section 4.2

Figure 4.3 Backup diagram for state value function.
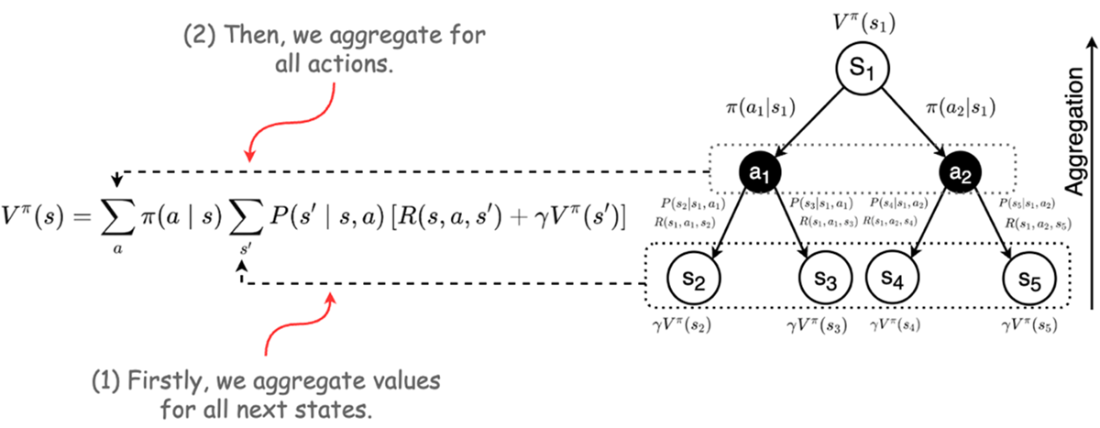
A backup diagram visualizes how future state values contribute to the current state's value. section 4.2


How Applied Reinforcement Learning covers it

How deep it goes
Defines γ through its role in Bellman averaging, without detailing numerical settings.
Examples
Uses a backup diagram to visualize how possible future states contribute to present value.
What you can do after
Understand how γ discounts expected next-state value in a Bellman calculation.
How it connects
Connects discounting to Bellman equations, state value, policies, and rewards.

Also explained in

Compare how 5 books explain discount factor →

Related concepts

This explainer was generated by Manning's knowledge graph from the text of Applied Reinforcement Learning. The section links point to the parts of the book it draws on.


