A distance-based algorithm detects unusual records by treating rows as points and scoring those with few nearby, similar records. It is primarily an unsupervised approach for numeric tabular data. section 3.2.1 section 3.2
Practical use depends on representation, scoring, and computational choices:
- Encode categorical features numerically and scale numeric features, commonly with min-max scaling or standardization, so large units do not dominate distances. section 3.2
- Score each record by the distance to its kth-nearest neighbor; averaging distances to several nearest neighbors can provide a more robust KNN score. section 3.2.1
- Use structures such as scikit-learn’s BallTree to avoid explicitly calculating every pairwise distance, which can become infeasible. section 3.2.1
- Treat flagged records as candidates rather than automatically meaningful anomalies, because parameter tuning is difficult without labeled data and high dimensions weaken distance measures. section 3.2.1 section 3.4
Synthetic clusters and inventory records
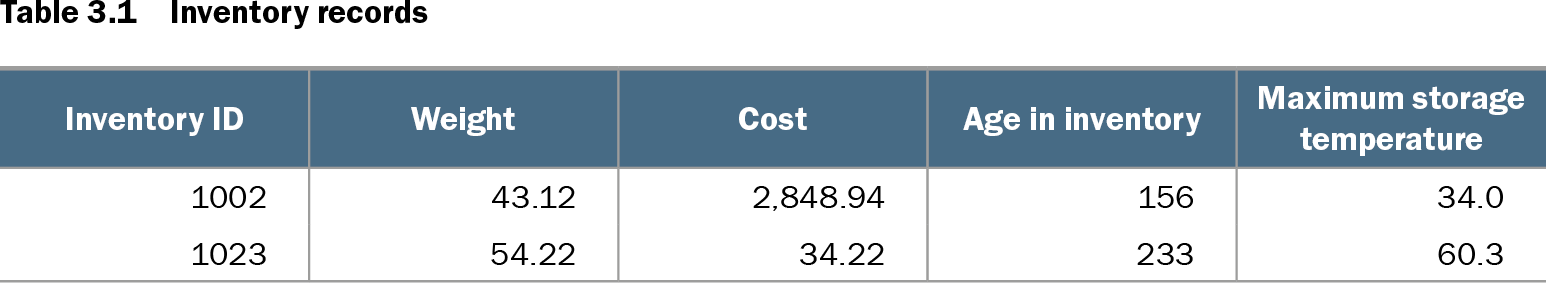
A two-cluster synthetic dataset can display outlier scores by changing point sizes and then labeling the top five or fifteen candidates. Inventory records illustrate why weight, cost, age, and storage temperature should be placed on comparable scales before neighbor distances are interpreted. section 3.2.1 section 3.2
Table 3.1 Inventory records (view table figure)
| Inventory ID |
Weight |
Cost |
Age in inventory |
Maximum storage temperature |
|---|---|---|---|---|
| 1002 |
43.12 |
2,848.94 |
156 |
34.0 |
| 1023 |
54.22 |
34.22 |
233 |
60.3 |
Inspect the inventory table to connect multidimensional records with the point-in-space view used by distance-based detection. section 3.2.1