When work items are independent, they can run at the same time without waiting for one another. For example, doubling each value in an array needs no item to wait for another. This is embarrassingly parallel: easy to divide among workers. It still takes time to schedule threads, access memory, and launch GPU work. section 1.4
Doubling an array
A sequential loop doubles one element at a time. A GPU can instead assign one thread to each of 1,000 elements so they are processed together. By contrast, summing values depends on running totals, so it is not embarrassingly parallel; parallel reduction combines partial results in rounds. section 1.4
Figure 1.2 Parallel processing: every element at once. A GPU assigns one thread per element, doubling all 1,000 values in parallel; the hardware schedules those 1,000 threads onto its many CUDA cores.
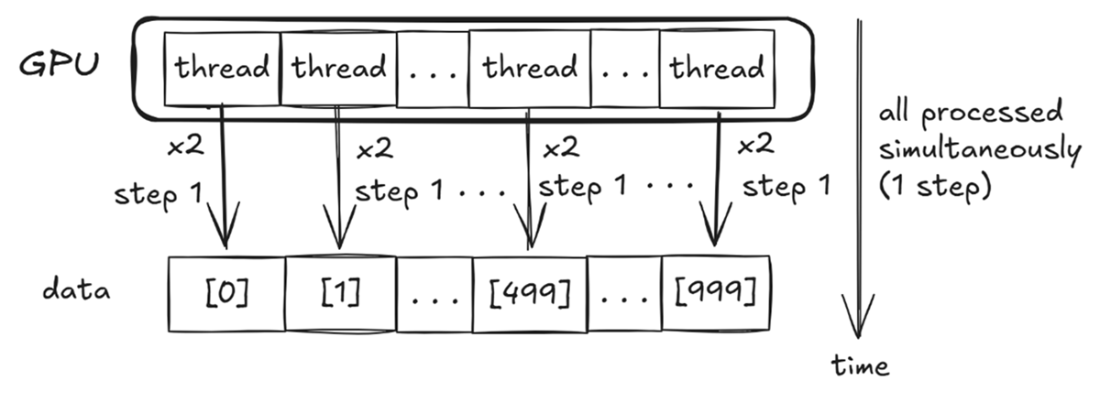
The figure shows one GPU thread assigned to each array element, with the hardware scheduling those threads onto CUDA cores. section 1.4


