Exactly-once delivery prevents retries or failures from producing duplicate processing effects, but only when the source is replayable and the processing path coordinates state, offsets, and commits. Apache Flink uses checkpointing and two-phase commit protocols with Iceberg’s atomic snapshot commits so a checkpoint’s changes become visible together or not at all. Non-replayable sources cannot provide the same guarantee, and the ingestion tool must still prevent conflicting changes or duplicates. section 6.1.2 section 6.4.2
Apply the guarantee with explicit operational tradeoffs:
- Track committed records with checkpoints so failures resume from a known state and retry only incomplete work. section 6.1.2 section 6.2.3
- Balance commit frequency against freshness and metadata overhead; streaming writers commonly commit buffered records in batches. section 6.2.3
- Treat late events, malformed records, and long-running state recovery as pipeline-design concerns rather than storage guarantees. section 6.2.3
Flink streaming into Iceberg
Define a Kafka source with a watermark, configure an Iceberg sink, and insert the source stream into the sink. With checkpointing correctly configured, Flink coordinates incremental commits with Iceberg snapshots for exactly-once delivery. section 6.4.2
Figure 6.3 By using checkpointing to track which incoming records have been committed successfully, the system knows which records to retry when a failure occurs.
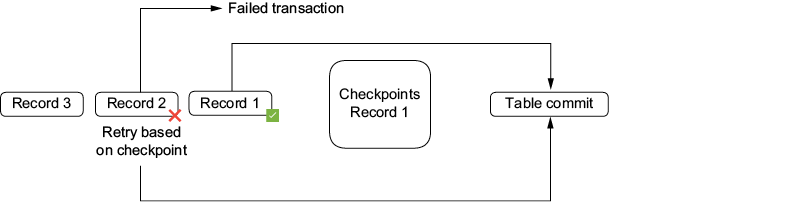
Use the checkpoint flow diagram to trace which records are already committed and which records must be retried after failure. section 6.1.2





