liveBook · Manning

Execution provider

As explained in Quantization and Fast Inference

An execution provider is an ONNX Runtime backend that assigns and executes model-graph operations on a particular hardware or software target.

An execution provider (EP) selects which kernels a runtime dispatches for model operations on target hardware. In ONNX Runtime, providers connect the serving runtime to backends such as CUDA, TensorRT, and OpenVINO. section 9.1

A provider without kernels for the target data type can cause a silent FP32 fallback. Verify the executing data type on the deployment host; a quantized model artifact alone does not prove quantized execution. section 9.1 section 9.6

Figure 9.1 Hardware selects the runtime family, and the execution provider selects which kernels dispatch. The leaf node is the production artifact. The two routes to TensorRT and OpenVINO, standalone versus via ORT, trade peak latency against a unified serving surface across heterogeneous fleets. Branches marked Chapter 10 and Chapter 11 point to regimes covered there.
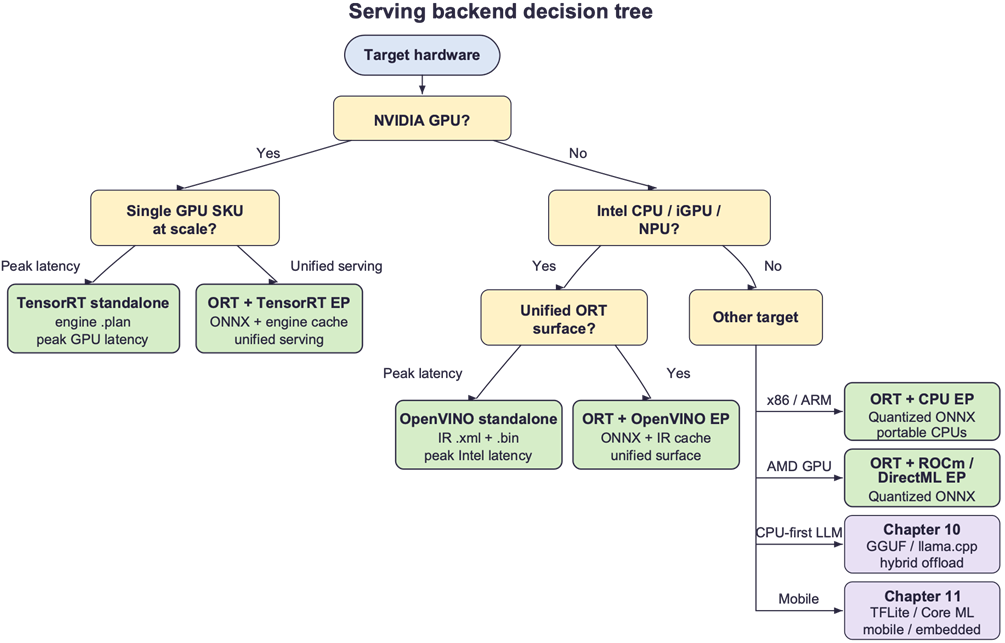
Trace how hardware determines the runtime family, the provider determines kernel dispatch, and the deployment route trades peak latency against a unified serving interface. section 9.1


How Quantization and Fast Inference covers it

How deep it goes
Explains provider selection as the kernel-dispatch stage and identifies silent FP32 fallback when target-dtype kernels are unavailable.
Examples
Names CUDA, TensorRT, OpenVINO, DirectML, ROCm, CPU, and TensorRT and OpenVINO provider configurations.
What you can do after
Diagnose whether target-dtype kernels actually dispatch by verifying execution dtype on the deployment host.
How it connects
Connects ONNX Runtime providers with CUDA, TensorRT, OpenVINO, DirectML, ROCm, and target-dtype kernels.

Also explained in

Compare how 2 books explain execution provider →

Related concepts

This explainer was generated by Manning's knowledge graph from the text of Quantization and Fast Inference. The section links point to the parts of the book it draws on.