An explore-only strategy randomly selects an action at every trial without using previous results. In a multi-armed bandit, it gathers information evenly but ignores estimated rewards, creating a clear exploration-only baseline. section 12.1.6
Three slot machines over 90 trials
Suppose three machines have mean payoffs of 8, 10, and 5. Randomly selecting each machine about 30 times produces an expected return of 690, compared with 900 from always selecting machine 2. The resulting regret is 210. section 12.1.6
Figure 12.7 Three slot machines as a noncontextual multi-armed bandit (MAB) problem. The payoff distribution’s mean and standard deviations of these three machines are (8,0.5), (10, 0.7), and (5, 0.45), respectively.
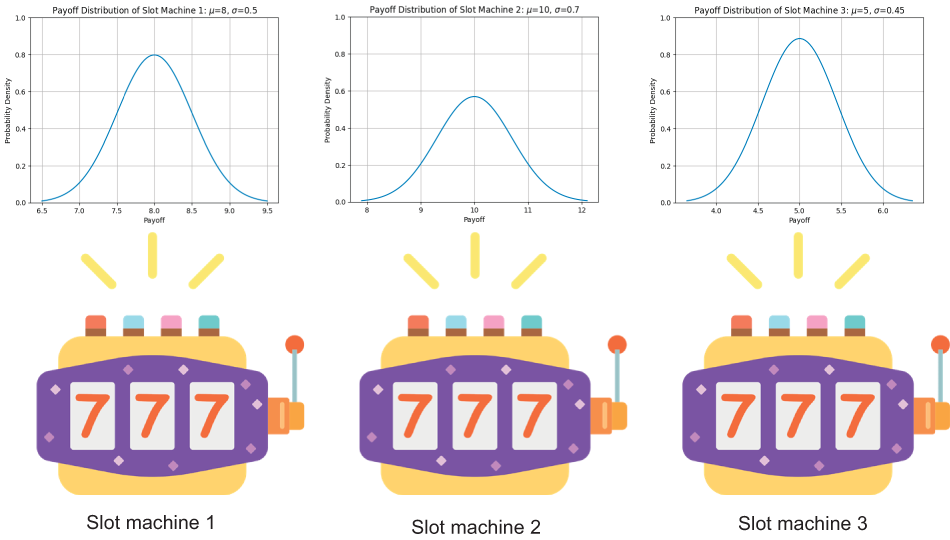
Compare the three arms’ payoff means and standard deviations before implementing the random-selection policy. section 12.1.6
