A filter method selects features independently from the model by ranking single-feature statistical properties or relationships among features. It provides a fast first pass before modeling or more expensive selection. section 11.3.3
Use filter methods in two main ways:
- Rank individual features by variance, granularity, consistency, or correlation with the target, then retain the top-N subset. section 11.3.3
- Compare features with rank correlation or mutual information to identify redundant pairs and remove one without expected performance loss. section 11.3.3
- Scale the method to high-dimensional data and use it before fitting a model or applying wrapper-based selection. section 11.3.3
Pre-training feature review
An automatic report can flag a high feature-interaction score as a warning that reducing one of two similar features may hurt model performance before training begins. section 11.3.3
Figure 11.8 Families of feature selection methods
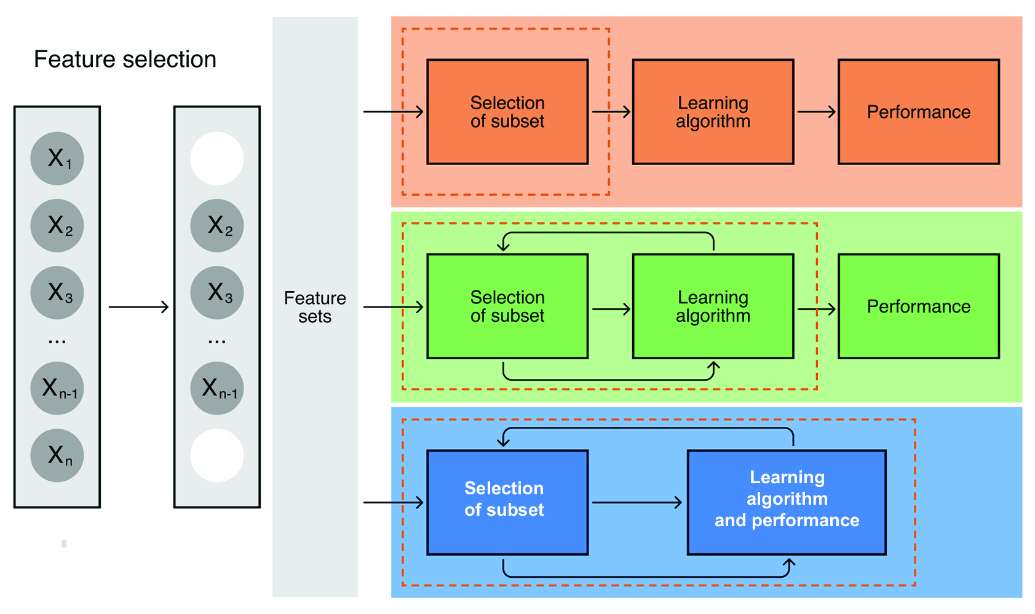
Compare filter methods with wrapper and embedded feature-selection families. section 11.3.3
