FlashAttention is an exact, IO-aware attention algorithm for transformer models. It fuses matrix multiplication, softmax normalization, and value weighting into one tiled kernel instead of materializing the full attention matrix in global memory. section 3.3 section 3.7
Each program instance processes a tile of query vectors, iterates over key and value tiles, and accumulates weighted outputs in shared memory and registers. This reduces global-memory accesses from quadratic to linear in sequence length; careful online accumulation of softmax statistics also improves numerical stability. Reported speedups over standard implementations are 2× to 4×. section 3.3
Figure 3.5 Kernel fusion in attention reduces memory traffic and idle time.
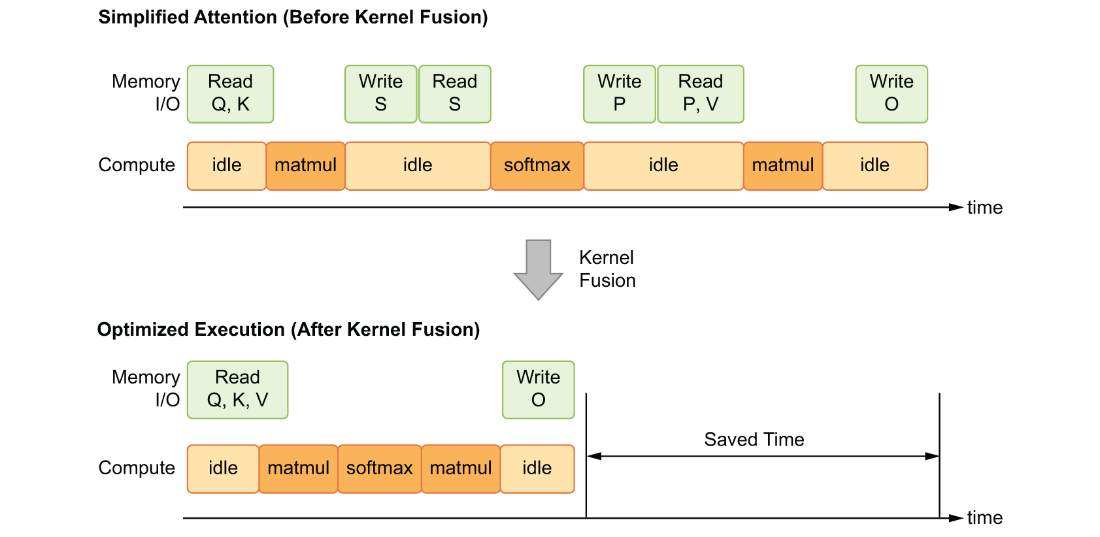
The figure summarizes how fusion in attention reduces memory traffic and idle time. section 3.3


