Data freshness measures how quickly newly generated or updated data becomes available for querying. It is a core ingestion metric alongside throughput and latency. section 6.1.1
Freshness requirements depend on the use case: fraud detection and real-time dashboards may need seconds, while financial close, daily reports, and regulatory exports may tolerate minutes or hours. section 6.1.1
Use freshness expectations to shape the ingestion architecture:
- Treat Apache Iceberg as an analytical sink rather than an OLTP system when workloads require sub-second visibility or continuous record-level updates. section 6.1.1
- Use Flink or Kafka-based pipelines for controlled low-latency continuous writes; use Spark for high-throughput scheduled or backfill ingestion with greater end-to-end latency. section 6.1.1
- Ask stakeholders how long reports, models, and dashboards can wait, then align freshness expectations with data quality, usability, and automation needs. section 4.1.2
- Account for freshness differences in federated systems, where direct source access can avoid nightly ETL but varying latency and source performance remain risks. section 8.1.1 section 8.2.1
Figure 6.2 If two systems process the same data, the one that can deliver it in less time has lower latency.
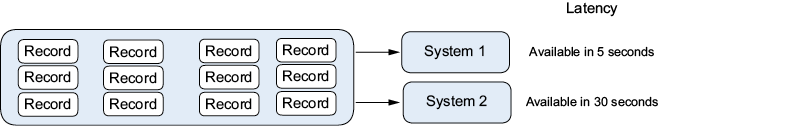
Compare freshness with latency by examining how quickly systems deliver processed data for querying. section 6.1.1


