The frozen lake problem is a discrete 4-by-4 grid-world in which an agent navigates safe frozen squares, avoids terminal holes, and reaches a rewarded goal. section 11.1.1
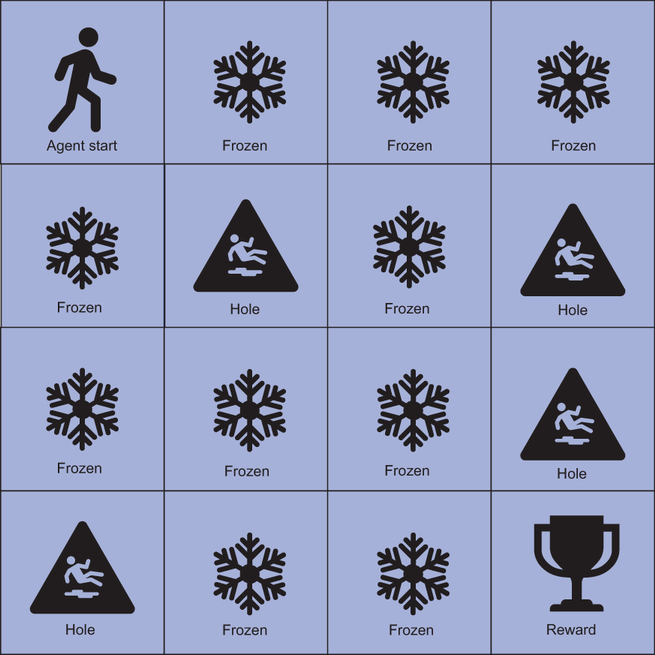
Use the environment diagram to inspect the grid layout, safe squares, holes, and goal location. section 11.1.1
A Q-learning agent solves the environment by:
- Selecting up, down, left, or right from each state. section 11.1.1
- Exploring through trial and error while estimating action quality in a Q-table. section 11.1.1
- Updating values from rewards and future-state estimates, then reducing random exploration over 20,000 episodes. section 11.1.1
Minimal Gym implementation
Create FrozenLake-v0 with Gym, derive its action and state counts, initialize Q to zeros, train with choose_action, env.step, and learn, then exercise the greedy policy for five episodes. section 11.1.1
