GPU utilization measures how much available GPU computation capacity is active during a workload. In model parallelism, sequential dependencies can leave most devices idle while one performs computation. section 4.4.2
Model-parallel underutilization
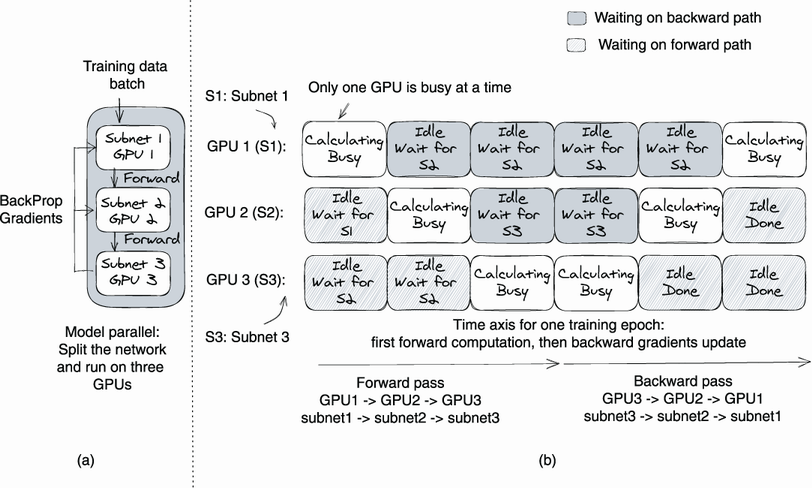
A three-GPU model split into sequential subnetworks activates only one GPU at a time during forward and backward passes, leaving each GPU idle for 66% of training time. Pipeline parallelism improves utilization by processing different microbatches simultaneously. section 4.4.2
Figure 4.7 Model parallel training can have severely low GPU usage. In this approach, the network is split into three subnets and runs on three GPUs. Because of the sequential dependency among the three GPUs, each GPU is idle 66% of the training time.
Use the utilization figure to compare sequential model parallelism with its severe idle periods. section 4.4.2
