Gradient ascent improves a policy by moving its parameters uphill toward higher reward. The gradient points toward faster improvement, while the learning rate controls the step size. section 9.2
For policy parameters θ, the objective J(θ) is expected cumulative reward. The update θ ← θ + α∇θJ(θ) moves the parameters toward higher expected return—the reward-maximizing counterpart to gradient descent. section 9.2
Figure 9.2 The Policy Gradient Objective.
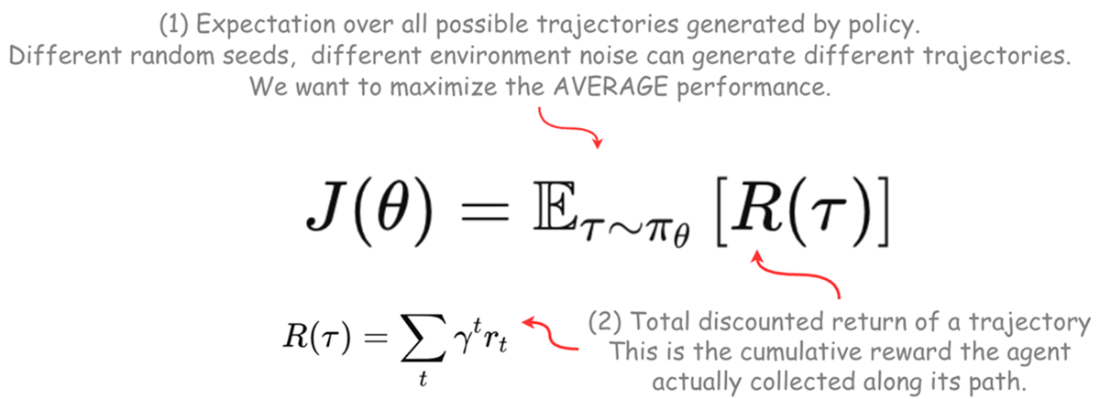
See the policy-gradient objective represented visually. section 9.2
