Greedy decoding selects the single highest-scoring next token at each inference step, turning an LLM’s final-position scores into deterministic text generation. section 2.6
Apply the method inside the autoregressive generation loop:
- Run the model on the prompt and previously generated tokens. section 2.6
- Keep the score vector from the final input position, because it predicts the next token. section 2.6
- Use torch.argmax(..., keepdim=True) to return the index of the largest score while preserving a concatenation-friendly shape. section 2.6
- Decode the resulting token ID and feed it back into the next generation iteration. section 2.6
Selecting the next token
Given the final score vector, torch.argmax(last_token, dim=-1, keepdim=True) returns token ID 20286; decoding that ID produces “Large.” section 2.6
Figure 2.10 Sequential (autoregressive) text generation in LLMs. At each iteration, the model generates the next token based on the input and previously generated tokens, which are cumulatively fed back into the model to produce coherent output.
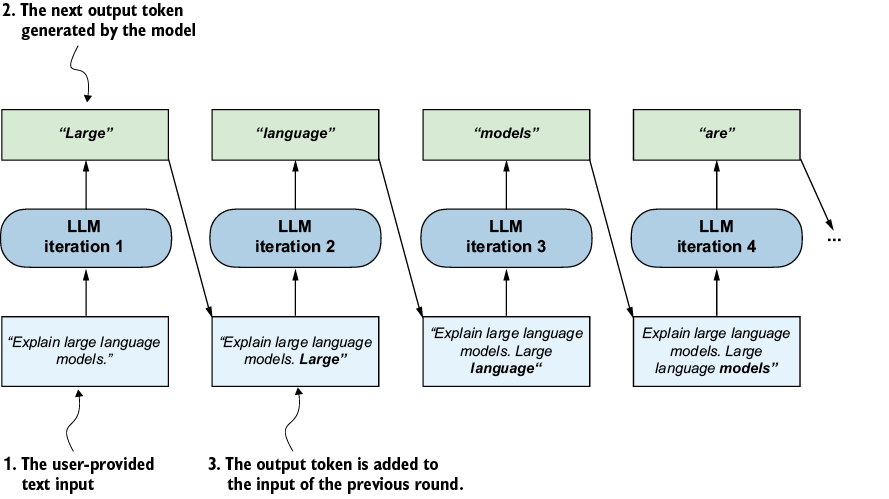
Trace how each selected token is appended to the context and reused to produce the next prediction. section 2.6











