Image captioning generates natural-language descriptions of image content. An encoder converts visual information into embeddings, and a decoder generates an English caption token by token. section 4.0 section 4.5
A captioning transformer follows this sequence:
- Prepare training examples as paired images and descriptive captions, adding <start> and <end> markers. section 4.1 section 4.5
- Encode each image by dividing it into patches and converting the patches into a sequence of image embeddings. section 4.0 section 4.5
- Feed the image embeddings and caption input sequence to a decoder that predicts the next token. section 4.1
- Train with shifted target sequences and cross-entropy loss, then update model parameters to improve predictions. section 4.5
- Generate captions autoregressively by starting with <start>, appending each predicted token, and stopping at <end>. section 4.1
Equivalent descriptions
A human caption might say, “two young girls are running through shallow water at a pool,” while a generated caption says, “two girls are running away from the water and laughing.” Different wording can still accurately describe the same scene. section 1.1.2
Figure 4.1 Eight steps to build a text-to-image generator from scratch. In this chapter, you’ll reinforce and apply skills from steps 1 and 2: building a transformer that captions images. The encoder is a ViT, similar to what you created for image classification in chapter 3. The decoder generates text based on image features, much like the decoder you developed for German-to-English translation in chapter 2.
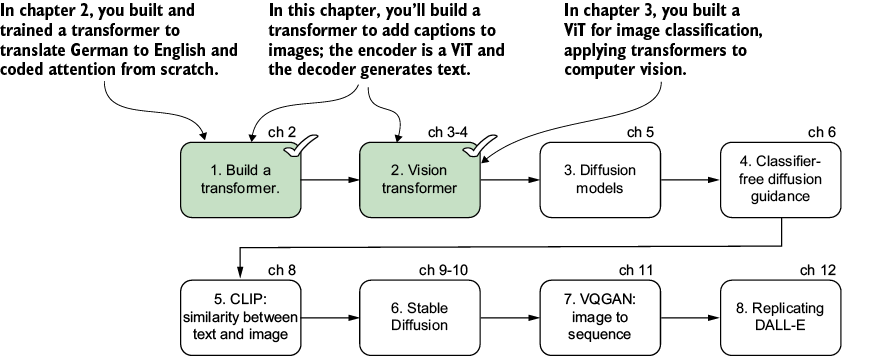
Use the architecture diagram to trace how a vision transformer encoder and text decoder form the captioning stage of a larger multimodal generation pipeline. section 4.0
