An inference request is a web API request that submits input to a deployed, trained model and returns a prediction. Prediction request and scoring request are equivalent terms; the API entry point executes the model algorithm in serving mode. section 6.1.5 section 10.0
In production, requests are served by a model service. The service uses a model identifier or handle to locate the required model artifacts and inference container, then produces an inference response while meeting expected request rates and latency. section 10.2.5 section 10.0
A request can drive a serving workflow that:
- Names a model by model ID, or by model name and version. section 7.5.2
- Causes a frontend or routing layer to retrieve model metadata and download model files to shared storage when needed. section 7.1.2 section 7.5.2
- Routes input to the appropriate predictor, which preprocesses data, executes the model, postprocesses output, and returns results. section 7.5.2
Intent classification request
A local prediction service can receive a gRPC request containing runId 1 and the document “merry christmas.” It loads the intent-classification model and returns the result “joy.” section 7.1.1
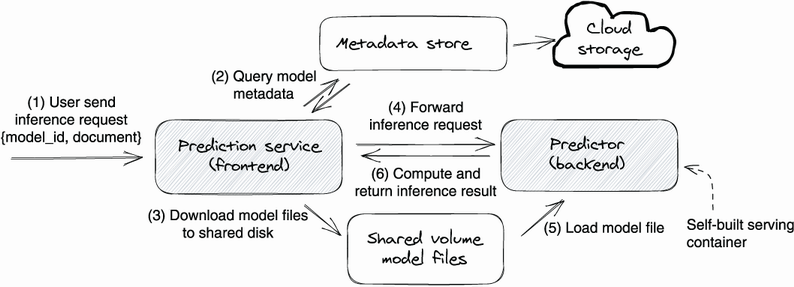
Trace the six-step path from a caller’s text and model ID through metadata lookup, shared model storage, predictor execution, and the returned prediction. section 7.1.2
