Intellectual property exposure occurs when an AI system is trained on copyrighted or proprietary data without authorization, creating legal, financial, and reputational risk. section 11.1.1
A customer’s proprietary material enters training data
DataMax trains models on a public dataset scraped from the web. A major customer discovers that its proprietary engineering thought leadership was included, creating potential exposure to lawsuits, fines, and reputational damage. section 11.1.1
Reduce exposure through disciplined data governance:
- Use datasets that are properly licensed or in the public domain. section 11.1.1
- Audit training data regularly and remove potentially infringing material. section 11.1.1
- Check provider usage policies and commercial-use rights before development. section 11.1.1
- Anonymize and aggregate data to reduce inadvertent inclusion of proprietary information. section 11.1.1
Figure 11.2 Data classification classifies data into multiple confidentiality levels for a differentiated security strategy.
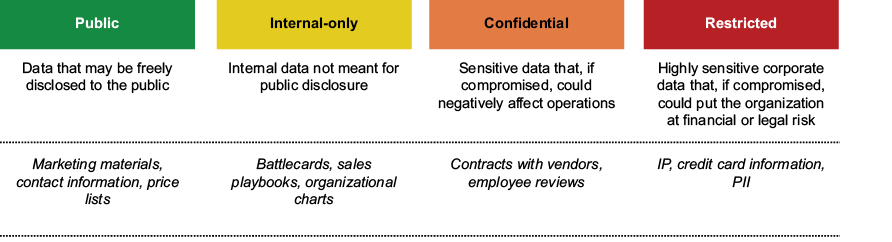
Data classification supports differentiated handling of confidential information, helping teams apply stronger controls where proprietary material requires them. section 11.1.1
