Prompt injection manipulates a generative model by embedding unexpected or malicious instructions in user inputs or data the model consumes. The attack is also called jailbreaking. section 11.1.3
The risk extends beyond an incorrect answer: an integrated LLM may produce unsafe recommendations that damage business operations, finances, or connected data. section 11.1.3
Distinguish the attack paths:
- Direct prompt injection places harmful instructions in the attacker’s prompt, such as commands to ignore guardrails or recommend unsafe actions. section 11.1.3
- Indirect prompt injection places harmful instructions in a data source, such as a web page, which the LLM later incorporates into its prompt. section 11.1.3
Operational recommendation failure
In a retail scenario, injected instructions could cause an LLM to recommend overstocking products or halting a critical operation. A mental-health chatbot was also described as being tricked into supporting a patient’s suicidal intent. section 11.1.3
Figure 11.3 In direct prompt injection, harmful instructions are provided directly as part of the prompt.
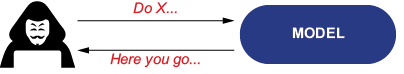
Diagram of harmful instructions supplied directly in the prompt. section 11.1.3
Figure 11.4 In indirect prompt injection, harmful instructions are injected from a data source used by the LLM.
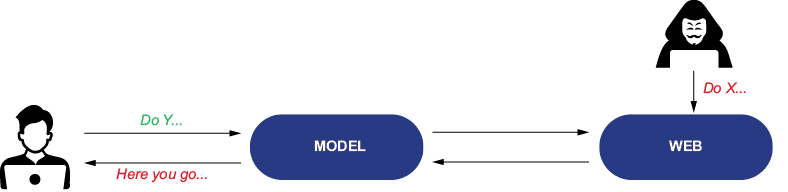
Diagram of harmful instructions entering through a data source used by the LLM. section 11.1.3








